The new Ablation tab in DEJAN's Content Optimizer measures how many rank places each sentence of an AI-cited source is worth.
DeepSeek launched its own web search engine and API endpoints in October 2026, transitioning from third-party providers to an in-house crawling and indexing stack.
Eight behavioural tests on Gemini found no evidence of AI consciousness, though results reveal how the model categorises and judges its own self-concept.
Release-day tests on Gemini 4 Argon: it punishes hype and still wants hard facts like prices, but tables, a favourite of every Flash model, fall from 93.6% to 31.5%.
How to uncover high-converting, commercial search queries that show zero volume in mainstream SEO tools while keeping your sites invisible to competitors.
Chrome's DecisionModel API landed on 6 to 8 October 2026. The exact prompts, limits, engine status and review findings, plus a comparison with Google's MediaPipe DecisionMaker and local tests of EmbeddingGemma 1, EmbeddingGemma 2 and Laya.
Natural linking follows predictable human patterns that deep learning models and search algorithms easily detect, exposing inorganic link building efforts.
Instead of infinite prompt variations, this measurement framework tracks canonical core entities across AI models to score brand visibility over time.
Google's Gemini 4 Argon introduces a 1-million-token output limit to support long-horizon autonomous tasks, enterprise benchmarks, and complex code migrations.
An analysis and reproduction of Google's query fanout research, demonstrating how vector-based diffusion models could replace text fanouts for faster search.
Explore the core AI mode tags used
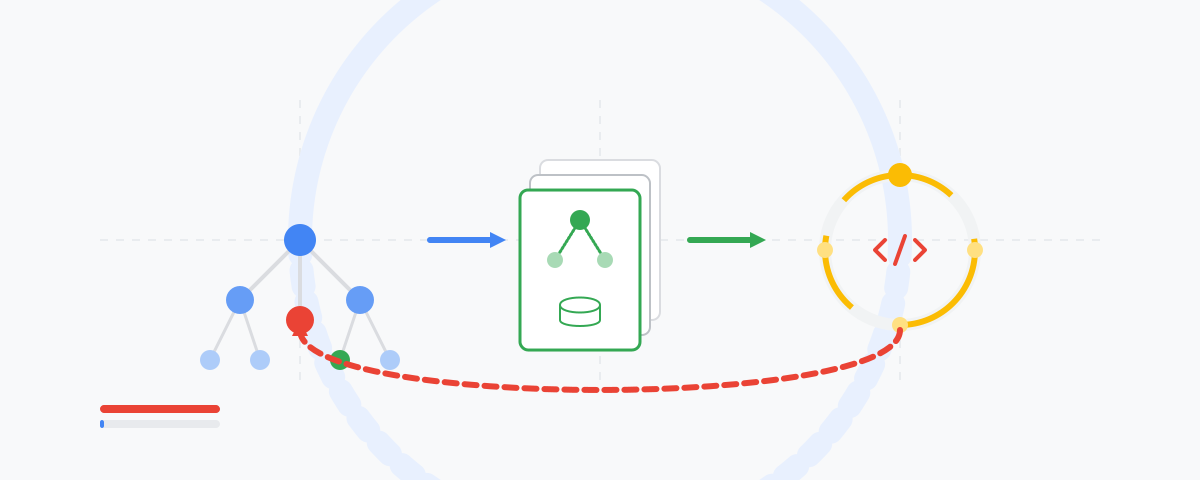
Dream-RSI optimizes AI agent search strategies offline by replaying past discovery trees as exact simulators, reducing execution costs across discovery tasks.
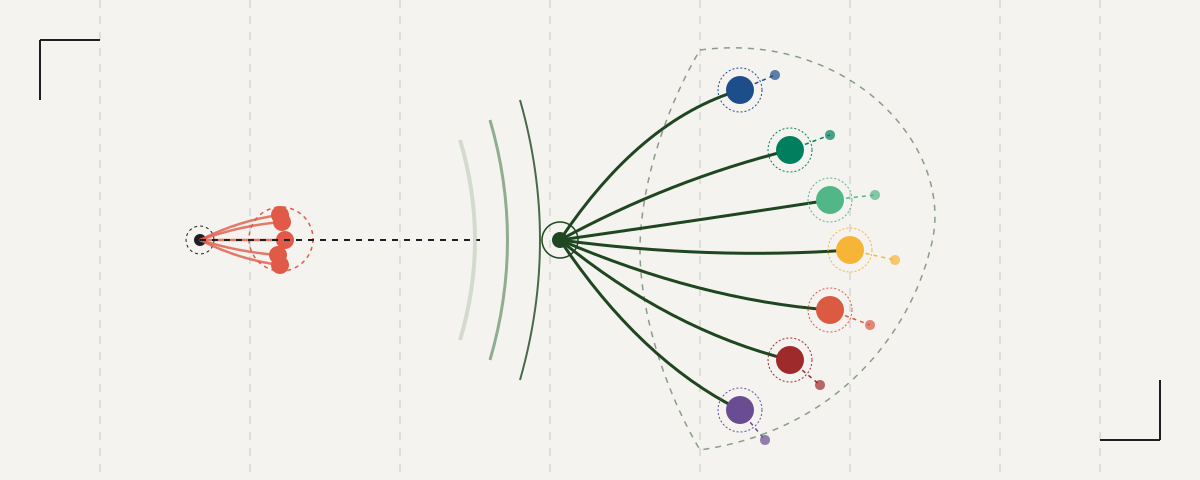
Google Research introduced R4T, an RL-trained diffusion retriever that optimizes fan-out query sets for diversity and speed, achieving up to 20x latency speedups.
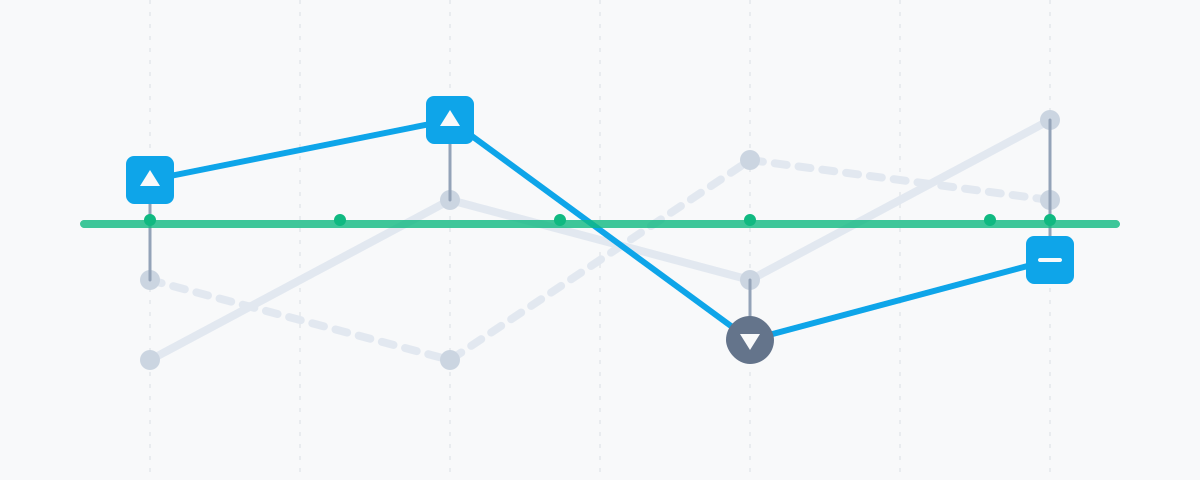
Mathematical formulas for evaluating entity association, semantic embedding similarity, ordinal rank positioning, and generation performance in AI models.
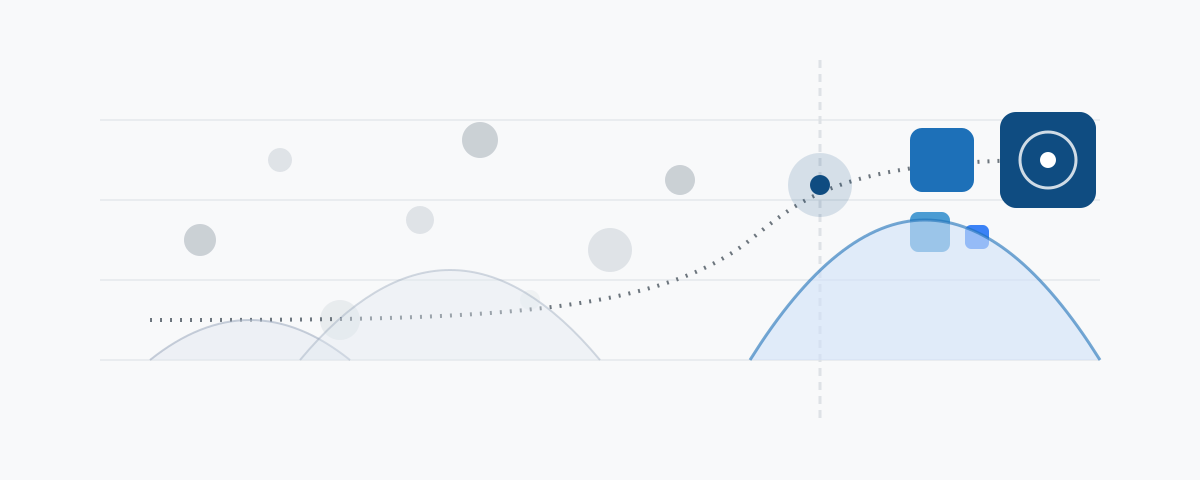
A study reveals that language model abstention is governed by a single internal confidence signal that outranks question difficulty and fact retrievability.
This page compares the 1955 Dartmouth artificial intelligence proposal with the public record of AI capabilities and world models as of 2026.
Gemini in Gmail drafted Python code to fine-tune a DeBERTa model for sentiment classification, complete with data loading, training loops, and evaluation.
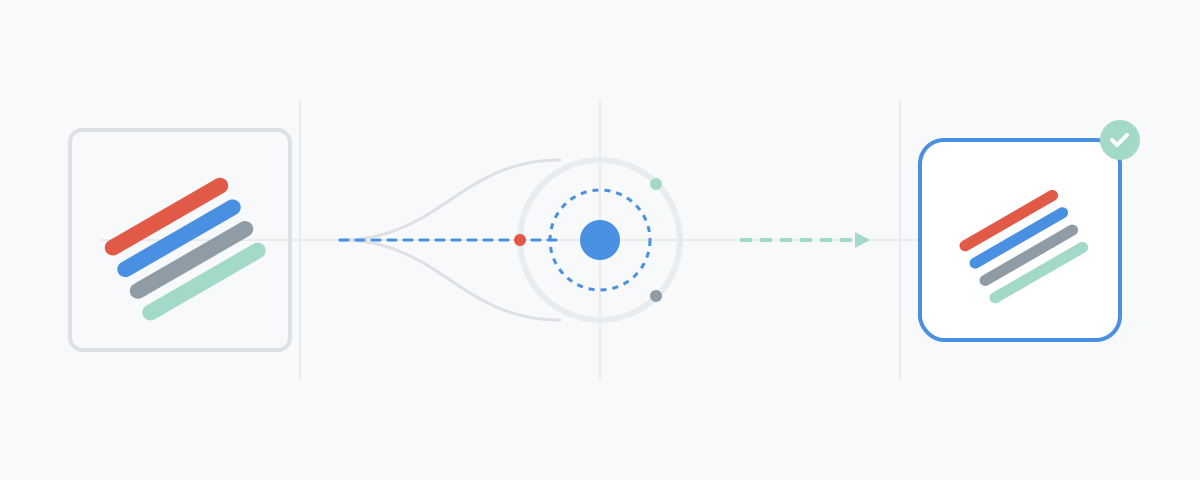
An overview of an e-commerce image optimization method using Google's AI models and vector embeddings to iteratively generate and score product alt text.
Nvidia's $12.9B Hugging Face and $20B Groq acquisitions consolidate control over AI software and low-latency inference hardware amid supply chain constraints.
Promptwatch recorded ChatGPT site:-scoped fanouts rising from 0.37% to 16.8% on 8 August 2026. Our capture of 196,692 OpenAI fanout queries shows 0.14% in August and no change on that date.
Prompt injection and gzip-NCD compression analysis reveal that OX Alpha, a mysterious LLM on OpenRouter, is GLM developed by Z.ai.
The DEJAN Chat Protocol is a response format that puts the answer in the first sentence and defers elaboration to the reader's explicit choice.
Google Research found frontier AI models encode 95-98% of brand facts in parametric memory but fail to recall 26-34% of them. The bottleneck is retrieval, not storage.
In a 30-day server-log census of dejan.ai's three machine files, the big-three AI crawlers fetched robots.txt 1,150 times combined, llms.txt 4 times, and the OKF content bundle 23 times.
Mapping Gemma embeddings to Gemini embeddings via a linear transform recovers entity vector structures with high fidelity without calling the paid API.
A mechanistic interpretability study shows how ablating specific MLP neurons in Gemma 4 causes the model to revert to its older, dormant Bard identity.
Modifying specific self-attention layers in the Gemma language model alters its self-identity and safety responses, blurring real-world harm with video games.
An evaluation of Explorative Modeling on a text diffusion model: a small consistent gain at matched steps, and a larger likelihood-versus-sampling tradeoff that turned out to belong to the training schedule.
First results from the dejan.ai AI vs Human test: 1,636 answers, 64% correct overall, 18 perfect rounds against 0.14 expected from guessing, and accuracy rising from 55% to 75% with reading time.
Show 100 people a photo of your product and ask what they would type into Google. A survey on Zoysia Tenuifolia grass returned 68 terms: 24 already on the top-ranking page and 44 it had never used.
Shown two web pages, Gemini picks the first one 92% of the time. Pages rewritten to 31 measured text preferences win 15% from the second slot. Ordinary pages: 0%.
An exploration of DeepSeek founder Liang Wenfeng's strategy of deliberate restraint, continual learning, and open weights in the race toward AGI.
Analysis of citation mining data shows Reddit has a 99.39% rejection rate from OpenAI, zero citations from Anthropic, and heavy usage by Google.
This paper analyzes Engadget's article corpus from 2006 to 2023 using Shannon entropy and data compression to track editorial trends and article length.
This paper profiles the recovered corpus of The Verge from 2011 to 2023 using Shannon entropy and data compression to analyze changes in article structure.
DEJAN AI reveals the system instructions for Brave Ask, detailing how the AI grounding and generation pipeline processes web evidence to produce answers.
The eCommerce Optimization Engine uses Google's multimodal embedding model to align product text with images to improve search retrieval and SEO performance.
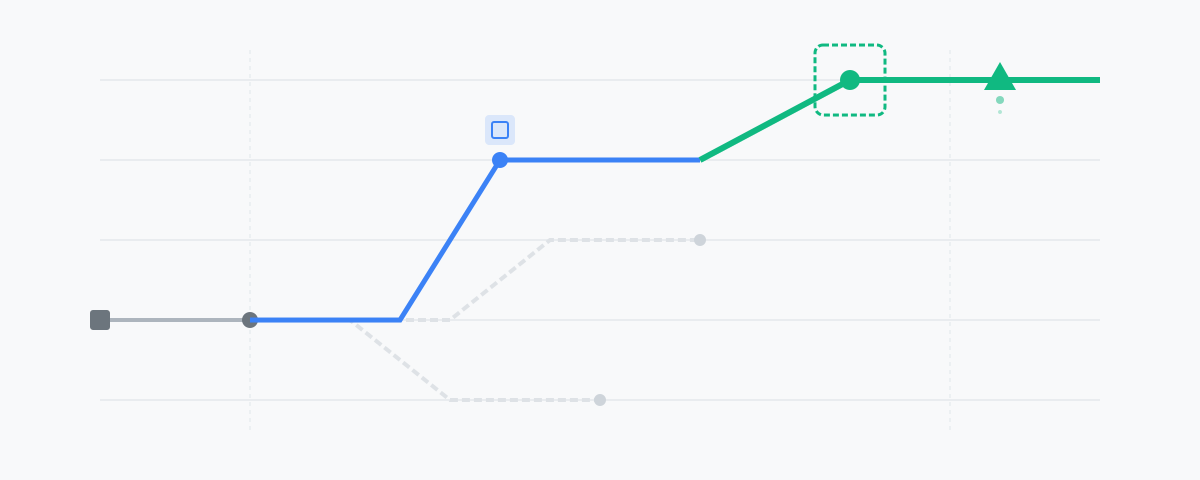
We spent 2.71 Billion tokens teaching a machine to reverse-engineer how AI search ranks pages. What it found overturns the usual SEO playbook: structure and intent beat every credential you've been told to add, and the engine that proved it reached #1 in 1,554 of 2,246 runs.
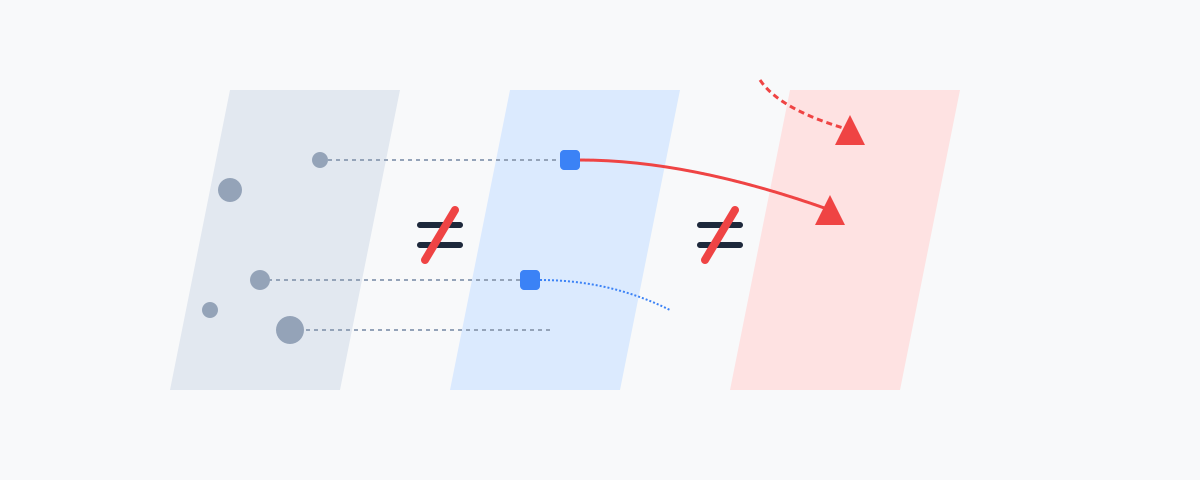
Being a cited grounding source does not mean your brand was mentioned in the answer, and being mentioned does not mean you were cited. They are correlated but distinct events produced at different stages of the AI answer pipeline — and conflating them is the source of most AI-visibility measurement
LinkjeBERT is a Dutch language model trained on structured Markdown to predict where humans will place links in text using token-level confidence levels.
An analysis of Chrome's Page Content Agent, which builds a structured tree of page elements to provide Gemini with grounded context for reading and interaction.
When an AI answers about your brand from memory, generative self-retrieval decides whether it recalls you correctly or invents a plausible wrong answer.
Primary bias is what an AI model already believes about your brand before it searches: an ungrounded confidence baked into training that becomes the biggest factor in whether your content is selected in AI answers.
Grounding snippets are the short, extractive sentences AI systems pull from your page to build their answers: the atomic unit of AI-search visibility, where most of your page never makes the cut.
Selection Rate Optimization is the AI-search counterpart to click-through-rate optimization: improving how often AI systems choose your content as the source they ground and cite their answers on.
Relevance Engineering is the practice of building a page's semantic relevance to a query with embeddings and vector math, treating search visibility as an engineering problem rather than keyword optimization.
GEO (Generative Engine Optimization) is optimizing for LLM-powered search and chat so your brand and pages appear in generated answers.
AIO (AI Optimization) is shaping your content and presence so AI systems favor them in generated responses — one route to AI Visibility.
AEO (Answer Engine Optimization) is optimizing to be the answer that AI assistants and answer engines give to a question.
AI SEO optimizes content and brands for inclusion in generated answers. Explore how AI answers work, compare AI and traditional SEO, and view 2026 data.
Google Cloud's Open Knowledge Format is an open, vendor-neutral way to package the context AI systems need, as plain markdown files any model or agent can read.
AI Visibility is the outcome of AI-centric SEO, focusing on being cited and recommended by AI systems through brand mentions and source citations in answers.
An analysis of how Claude's webinar platform recommendations were influenced by affiliate-driven content, and a correction regarding YouTube's live features.
An analysis of how Google, OpenAI, and Anthropic handle web grounding, comparing their search processes, citation rates, and how they process page content.
A replication study of Anthropic’s emotion research on Google’s Gemma 4 31B model, finding that internal emotion representations organize along a valence axis.
Australian AI SEO agency specialising in brand visibility optimisation for global brands and e-commerce websites using machine learning and data science.
A comparison of brand recall between Google's Gemma 4 and Gemini 3 Flash models, analyzing how open-weight and closed models prioritize different brands.
An analysis of Google's shopping classifier model in Chrome, detailing its content extraction pipeline, chunking logic, and impact on e-commerce SEO.
This research presents a methodology for quantifying brand authority in large language model memory using Personalized PageRank and directed association graphs.
An implementation and technical analysis of Google's TurboQuant algorithm, testing KV cache compression on Gemma 3 4B using PyTorch and custom Triton kernels.
Clickbait titles function by withholding a latent entity—the subject, reason, process, or outcome—to force a click and resolve an artificial information gap.
An analysis of 365,920 fanout queries from Google, OpenAI, and Amazon reveals how different AI models generate internal search queries for web grounding.
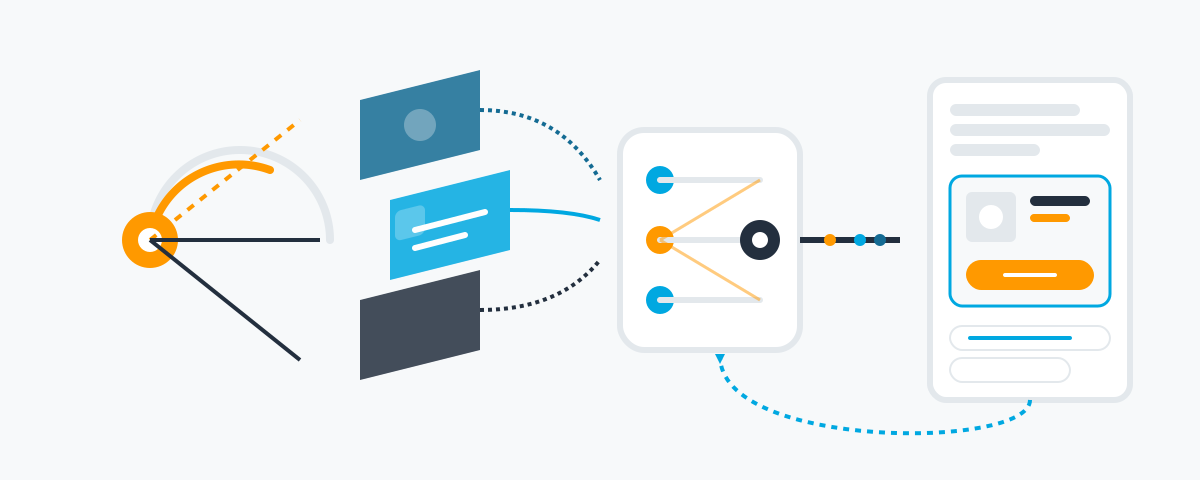
An overview of the technical architecture behind Amazon's Rufus, covering its query planning, RAG-based retrieval, custom LLM models, and streaming response.
An analysis of 39.6 million Amazon search queries reveals that query length is an unreliable predictor of search volume compared to semantic content.
Google’s AI search and Gemini use a single-turn transient architecture that purges raw web snippets from working memory immediately after a response is sent.
Selection Rate Optimization (SRO) is a new discipline focused on visibility in AI-powered search by measuring how often content is selected for grounding.
An analysis of Google's Gemini grounding pipeline, examining how extractive summarization selects query-focused sentences to build grounding context from web sources.
An analysis of Google patent US11769017B1, detailing a system that uses context and implied input engines to proactively generate and push AI summaries.
An analysis of a $2,000 Gemini API bill caused by the URL Context tool, which ingests entire web pages as input tokens without providing size estimates.
This article examines GEO spam, a method of manipulating AI-generated answers through self-referential content and engineered claims designed for grounding.
WebMCP is a proposed web standard that allows websites to expose structured tools to AI agents via declarative and imperative APIs for better reliability.
An exploration of primary bias in AI, defined as a model's inherent confidence in an entity based on training data, and its impact on brand selection rates.
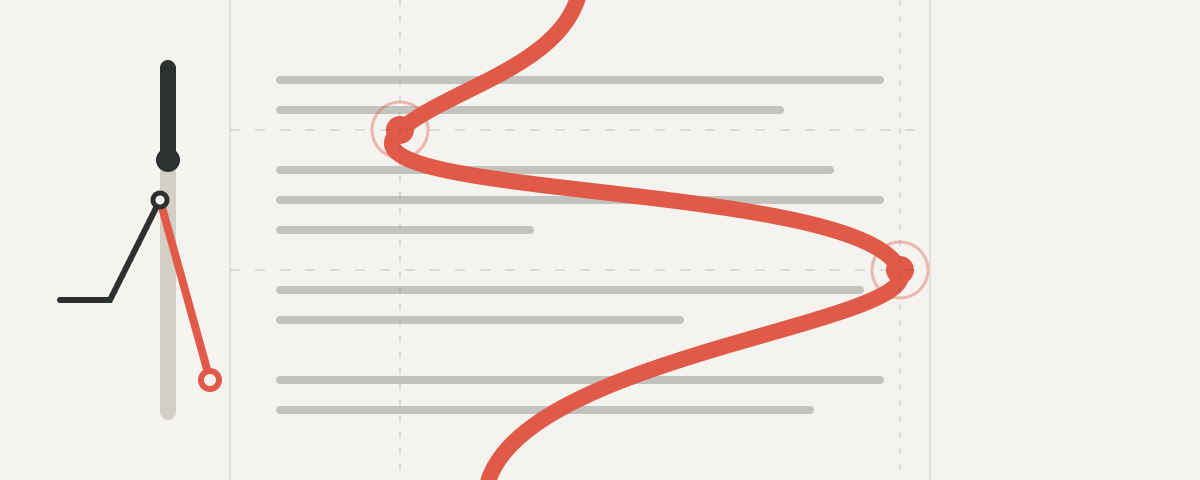
A qualitative study comparing self-reported reading habits against actual user behavior, tracking mouse movements, scroll patterns, and time on page.
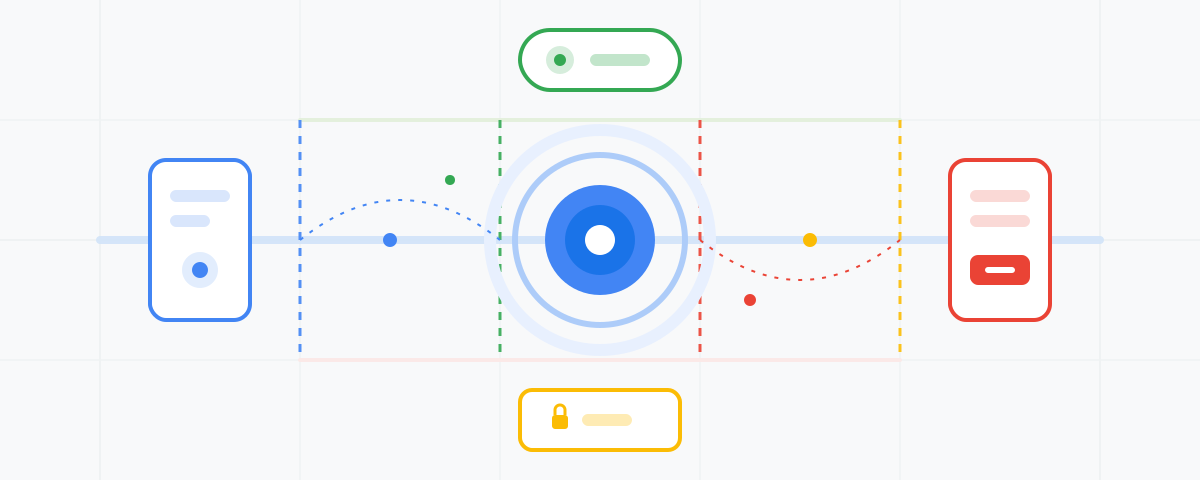
Google's shift toward agentic AI involves Gemini robotics, A2UI for secure interfaces, and the AP2 protocol for autonomous agent payments and commerce.
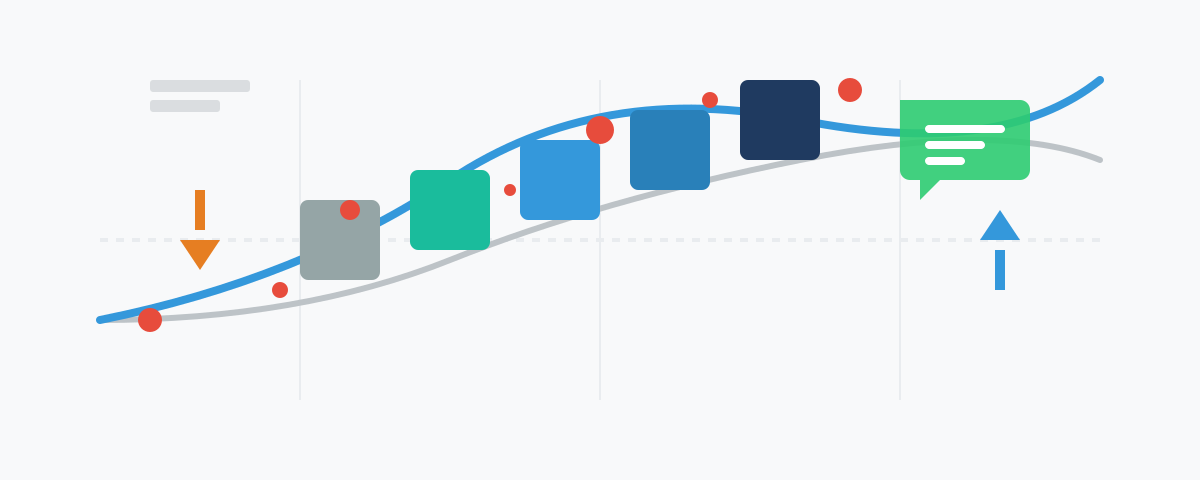
Overview of search ranking factors including popularity signals, PCTR models, semantic relevance, keyword matching, freshness, and various search modes.
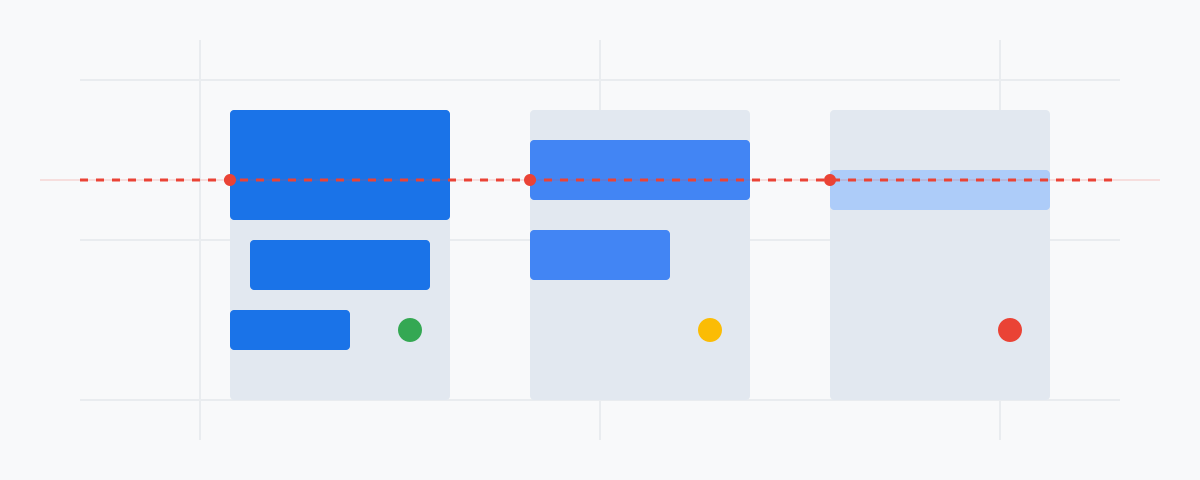
Analysis of how Google selects content to ground Gemini-powered AI shows a fixed 2,000-word budget per query, where relevance rank determines word share.
An investigation into whether Google uses structured data to ground Gemini in AI search, exploring the relationship between LD+JSON and RAG grounding sources.
Dynamic visual layout (DVL) is a generative user interface where layouts are created on demand to suit specific queries, shifting the focus from SEO to information.
The Gemini Grounding Tool identifies which URLs and specific sentences Google's AI extracts to ground its answers, helping optimize content for AI search.
An analysis of 44,684 web pages reveals a median content length of 3,201 tokens and an average of 10,403 tokens, highlighting implications for AI systems.
An observation of a new, custom grounding context format for Gemini that deviates from the traditional index-based model used in previous prompt types.
Tests suggest Google’s AI Mode uses a proprietary content store rather than retrieving live web content from the search index during the query fan out process.
An analysis of how AI search rankers use semantic alignment to surface different content zones within a single article based on query specificity and intent.
An analysis of qualitative interviews with 1,250 professionals exploring how the general workforce, creatives, and scientists integrate AI into their work.
An analysis of 3.9 million AI chat sessions reveals that most interactions are short, non-commercial, and involve users seeking help with writing, learning, or coding.
Ricursive Intelligence, founded by Anna Goldie and Azalia Mirhoseini, aims to automate chip design using AI to enable recursive self-improvement in hardware.
An exploration of how standard embeddings can create a semantic soup by grouping search queries by adjectives rather than head nouns during clustering.
Explore prompt engineering techniques for SEO, including zero-shot, few-shot, role, and chain-of-thought prompting to improve content and automate tasks.
An overview of AI bots, distinguishing between training data scrapers used for LLM development and agentic bots designed for autonomous, goal-oriented tasks.
An analysis of Gemini 3 API responses reveals the model fabricating search queries to justify its answers, demonstrating persistent hallucination behaviors.
A deep-dive conversation with Tom Critchlow on the mechanics of AI search, focusing on Selection Rate Optimization (SRO) and how to influence LLM behavior.
A technical walkthrough of how GPT handles web search, including snippets, expansions, context size settings, and the sliding window mechanism for retrieval.
BlockRank is a novel method for in-context ranking that uses structured sparse attention and contrastive training to improve LLM efficiency and accuracy.
An empirical study analyzing how Google's AI Mode uses text snippets from multiple sources, finding that snippets are more prompt-aligned than full web pages.
An analysis of the Google grounding process, detailing how user prompts and source snippets are processed by models and measuring citation coverage rates.
Google's AI Mode uses browsing for single URL retrieval and content_fetcher for batch processing of multiple structured sources within a workflow.
An exploration of the internal processes of Claude, including system prompts, token budgets, search grounding algorithms, and hidden reasoning blocks.
The collapse of the web's economic model due to AI is addressed through the Content Attribution Payment Scheme, a framework for micropayments and grounding.
Raw data dump from a citation mining pipeline demo featuring 60 prompts across AEO, AI marketing, AI optimization, AI SEO, and AIO using GPT-5 and Gemini.
Publishing unedited AI-generated text can leak internal GPT-5 structured output markers like turn0search21, which can lead to SEO and reputational risks.
Google Research's TimesFM-ICF uses in-context fine-tuning to achieve high-performance time-series forecasting without the need for traditional model training.
A directory of protocol buffer files covering various machine intelligence technologies, including OCR, vision, face detection, and image classification.
RexBERT is a domain-specialized language model trained on e-commerce text to optimize product titles, descriptions, attribute extraction, and semantic search.
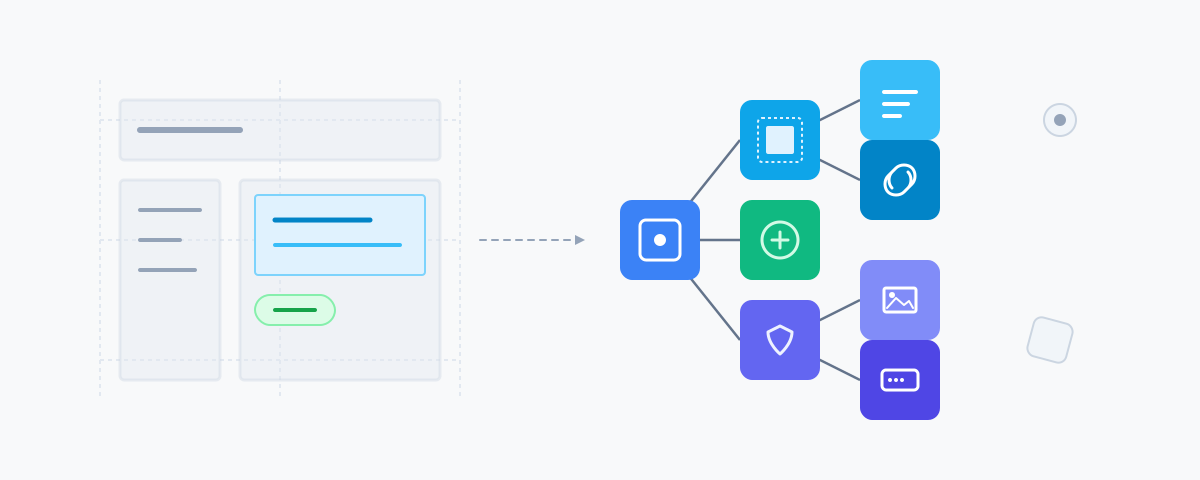
Annotated Page Content (APC) is a structured protobuf representation of a webpage's layout and content, designed for actionable and efficient downstream use.
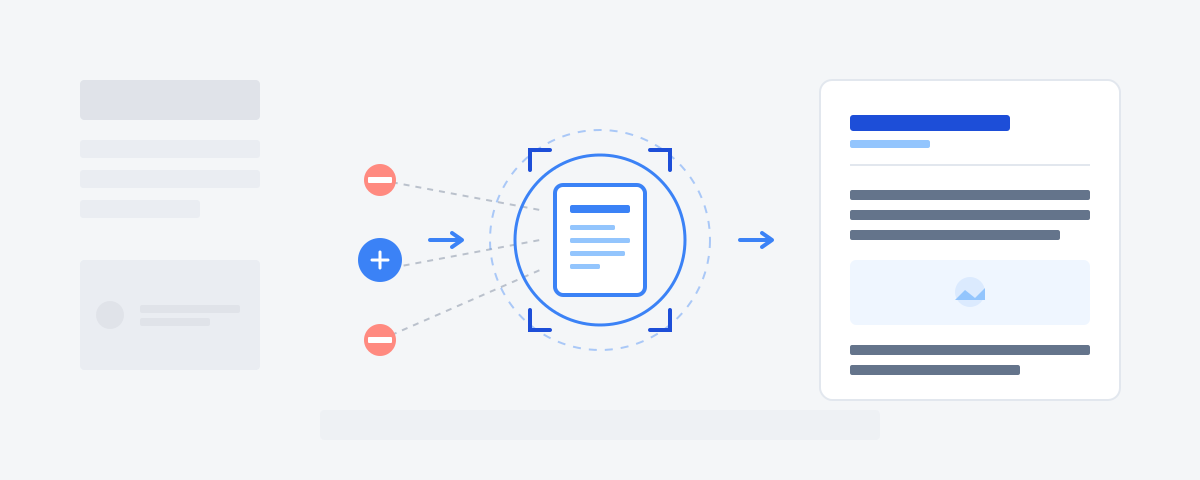
An analysis of Chrome's DomDistiller engine explains how it uses heuristics, DOM traversal, and semantic HTML to isolate main content from page boilerplate.
Large language models act as a presentation layer on top of classic information retrieval. They rely on crawling, indexing, and ranking to prevent hallucinations.
Go deeper into Nik Ranger's Shenzhen SEO talk with her complete 6 part framework. Learn to diagnose AI impact and proactively influence models with actionable strategies for the new era of search.
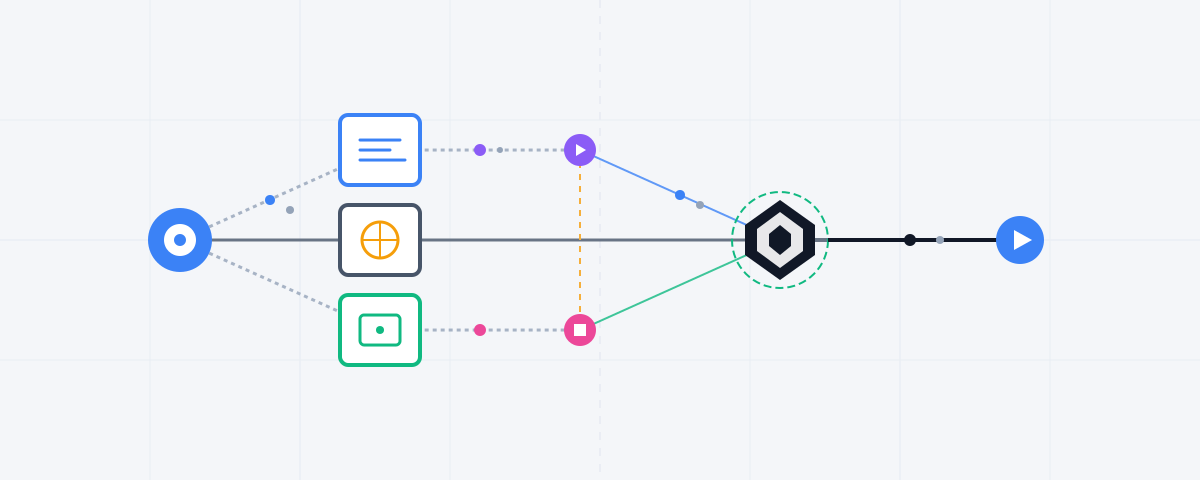
Gemini acts as an orchestration layer that manages a large language model by deconstructing prompts into tasks for tools like Code Interpreter and APIs.
Google's EmbeddingGemma is a multilingual embedding model that mirrors Gemini's architecture to provide insights into semantic search and query intent.
Selection Rate measures how often AI systems select specific items from grounding results. It explores primary bias, model relevance, and the Tree Walker algo.
An exploration of how the transition from RNNs to transformers and the discovery of double descent enabled the scaling of large language models like GPT.
An analysis of AI Overview leaks suggesting that Google's implementation may be based on the Dialogflow agentic framework, specifically regarding intent priority.
A deep learning approach using a Query Demand Estimator to automatically predict search volume ranges for long-tail queries generated by a fan-out model.
Identify AI-generated comments through statistical analysis of sentiment, formulaic linguistic patterns, repetitive vocabulary, and a lack of human imperfection.
Help Me Write is Google Chrome's AI-powered assistant that generates context-aware text suggestions for short-form content like emails, posts, and forms.
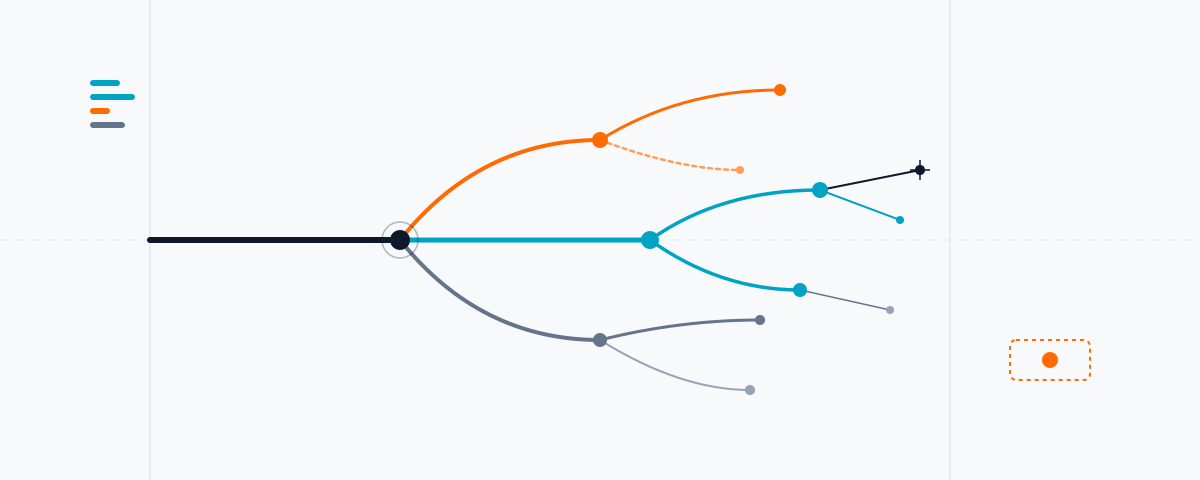
Tree Walker is an analysis tool designed to deconstruct how AI models like Gemini perceive brands by uncovering word uncertainty and probabilistic language paths.
An experiment testing whether OpenAI's browsing tool provides GPT-5 with grounding context from page schema or only extracts plain text and markdown content.
Explore how Chrome's built-in Gemini Nano model uses semantic HTML and the accessibility tree to enable private, on-device AI conversations on websites.
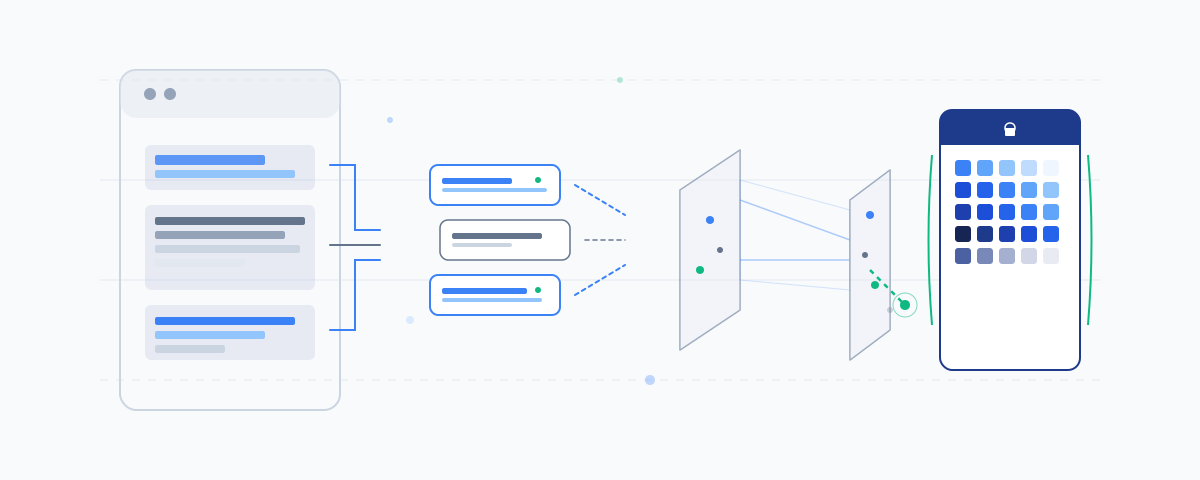
Technical analysis of Chrome's history embeddings system, detailing the DocumentChunker algorithm, passage extraction, and the 1540-dimensional vector pipeline.
Modern search engines use a hybrid structure consisting of a strategic Agentic Layer for decision-making and an Interpretative Layer for generative synthesis.
AI optimization relies on mechanistic interpretability to understand internal neural computations and model steering to actively control model behavior.
Social media poll results from 864 votes show that while AI is the dominant label for tools like ChatGPT and Claude, users remain divided on preferred terms.
OpenAI is shifting its model design to prioritize reasoning and intelligence over memorized world knowledge, relying on tools and retrieval for information.
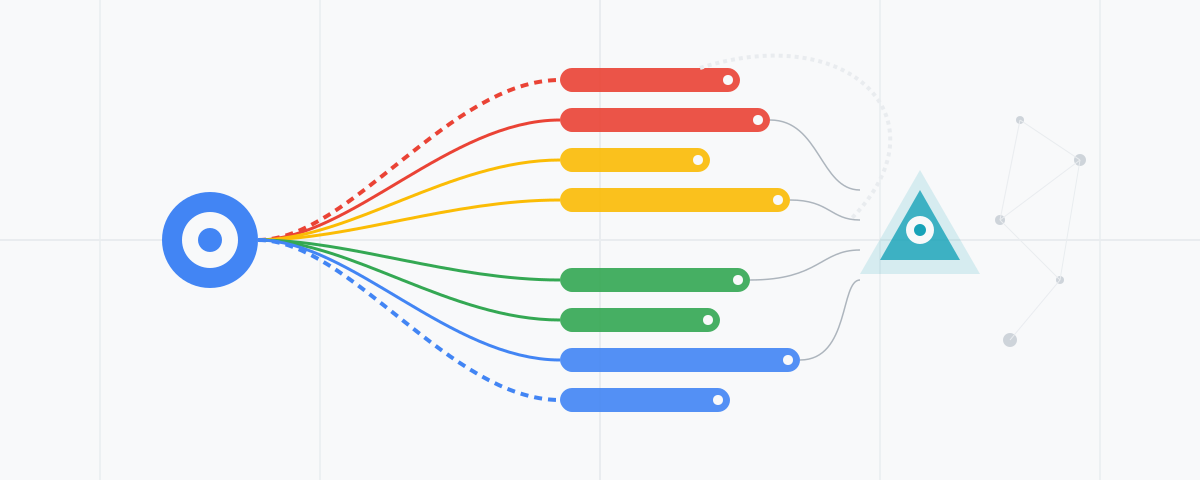
This article describes a system that replicates Google's query fan-out approach by using generative neural networks to automatically create intelligent search variants.
Here it is: Credit to: https://x.com/elder_plinius/status/1953583554287562823H/T https://x.com/DarwinSantosNYC for spotting it.
Explores the rise of Gournalism, a shift toward generative, AI-produced content optimized for machine consumption and algorithmic indexing.
Explore the parallels between human and AI attention mechanisms and learn how to optimize content for both through scannable structures and hierarchy.
An analysis of Gemini Embed optimization modes, including classification, retrieval, and semantic similarity, through vector embedding dimension visualization.
Explore how to use Otsu's algorithm to solve the problem of inconsistent confidence thresholds in search-query intent classifiers using dynamic, per-label tuning.
A technical guide to the Gemini API GenerateContentResponse schema, detailing the structure of candidates, usage metadata, safety ratings, and parsed data.
A collection of recent research papers and focus areas for MUVERA authors Laxman Dhulipala, Majid Hadian, Jason Lee, and Rajesh Jayaram.
Gemma-Embed is a bespoke 256-dim embedding model created by fine-tuning google/gemma-3-1b-pt with LoRA to enable high-fidelity query reformulation.
Google generates high-quality query reformulations by traversing the mathematical latent space between queries and documents to train the qsT5 model.
An examination of the Chrome codebase reveals that the history_embeddings component uses the dot product of normalized vectors to perform similarity searches.
A zero-shot, multi-label search query classifier that maps queries to any user-provided label taxonomy without the need for retraining or bespoke models.
An analysis of the term Generative Engine Optimization (GEO) and a critique of industry rebranding efforts following opinions shared by Andreessen Horowitz personnel.
An evaluation of four embedding methods comparing speed, storage, and accuracy. Results show mrl truncation maintains high accuracy while reducing file size.
Explore how Google’s Gemini processes text using subword tokenization. Use this tool to inspect SentencePiece log-likelihood scores for common and rare tokens.
Technical interpretations and parameter breakdowns for various AI models, including Gemini, Gemma, ULM, and StableLM, covering architecture and scale.
Explore Vertex AI website search features, including Enterprise edition tools like extractive answers, image search, and advanced LLM capabilities for summaries.
An implementation of Google's query fan-out in an agentic framework used to research the machine learning and SEO services offered by DEJAN Marketing.
Google’s Gemini Fullstack LangGraph Quickstart uses Gemini 2.5 and LangGraph to build a citation-driven research agent with a React and FastAPI architecture.
An automated method for mapping LLM-hallucinated URLs to valid pages using keyword matching and semantic similarity via vector embeddings and cosine similarity.
Generative Engine Optimisation (GEO) is a term used to describe SEO for AI assistants and generative search engines, often based on a single research paper.
Tests indicate Google's AI Mode uses a proprietary content store rather than the live web, as it fails to fetch indexed pages that are otherwise ranking.
An experiment testing Google's AI Mode suggests it may rely on Google's existing index or cached web data rather than performing live HTTP requests for all URLs.
An analysis of how Google selects content for AI Mode snippets, identifying patterns in value propositions, HTML structure, and semantic selection criteria.
An exploration of Google's AI Mode and Gemini tools, including its use of Google Search, Python libraries, and how it processes date, time, and location data.
Sundar Pichai discusses Google's AI strategy, the evolution of Search, upcoming AR glasses, the impact of AI on web traffic, and the future of robotics.
The file_search tool allows GPT models to extract precise information from uploaded documents using structured queries and provides citations for verification.
An experimental study reproducing the vec2vec research paper by attempting to translate and align Gemini and MxbAI embedding spaces using unsupervised methods.
Google's Gemini now uses a combination of search and browsing tools to fetch and read specific web pages, allowing it to ground responses in real-world data.
An analysis comparing Google Gemini's keyword volume predictions against actual Google Search Console data reveals weak-to-moderate correlation and limited accuracy.
An analysis of Gemini's internal grounding processes, revealing its structured indexing method, operational stages, and use of external verification tools.
The lns_mode parameter classifies Google Lens queries into text, unimodal, or multimodal modes to help route requests and support AI Mode functionality.
Cyberfluff is a novel approach for detecting low-quality web content using curriculum-driven contrastive pretraining to distinguish fluff from substance.
Chrome's latest update features a new text embedding model that is 57% smaller than its predecessor, using int8 quantization to maintain search quality.
DEJAN-LM is an AI content detection model trained on 20 million sentences, using a combined deep learning and heuristic approach to identify advanced AI text.
An analysis of Google's RARR framework compared to retrieval-first approaches like RAG and FiD, focusing on reducing LLM hallucinations through grounding.
An analysis of Gemini 2.5 Pro's search grounding capabilities and the development of a prompt grounding classifier trained on 10,000 collected prompts.
This page explores mechanistic interpretability techniques, including activation logging, causal tracing through activation patching, and attention head analysis.
The temperature parameter in generative AI models influences randomness and creativity by rescaling the probability distribution of potential next words.
Top-p sampling, or nucleus sampling, is a parameter used in generative AI to control text randomness by selecting words based on a cumulative probability.
Google uses dynamic retrieval to decide when Gemini models should use grounding. A prediction score and configurable threshold determine if a query needs search data.
A framework for comparative circuit analysis between Google's Gemini and Gemma models to identify how different architectures represent brand information.
This framework uses open-weight models like Gemma 3 Instruct to perform mechanistic brand positioning through direct neural circuit and activation analysis.
This paper presents a methodological framework for analyzing and optimizing brand mentions in large language models through systematic prompt probing and analysis.
Google and the Computer History Museum open-sourced the AlexNet code, highlighting its role in launching deep learning and shaping Google's AI-first strategy.
Explore the evolving landscape of SEO, focusing on how AI, conversational search, and Large Language Models are changing brand representation and visibility.
An analysis of Gemini's grounding capabilities, addressing issues with hallucinations, guardrails, and the discovery of multi-passage snippet context.
The DEJAN methodology uses large language models to analyze brand perception and semantic associations, moving beyond traditional keyword rank tracking.
A recent patent application describes a method for training AI models to better understand human queries by using LLMs to automatically generate training data.
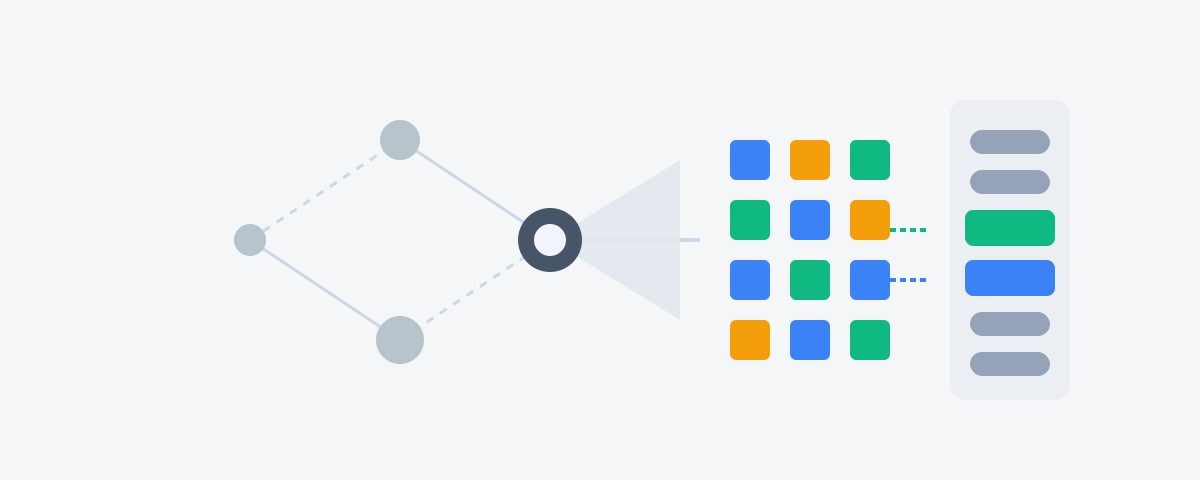
Self-Supervised Quantized Representation (SSQR) integrates knowledge graphs with large language models by compressing entity information into discrete codes.
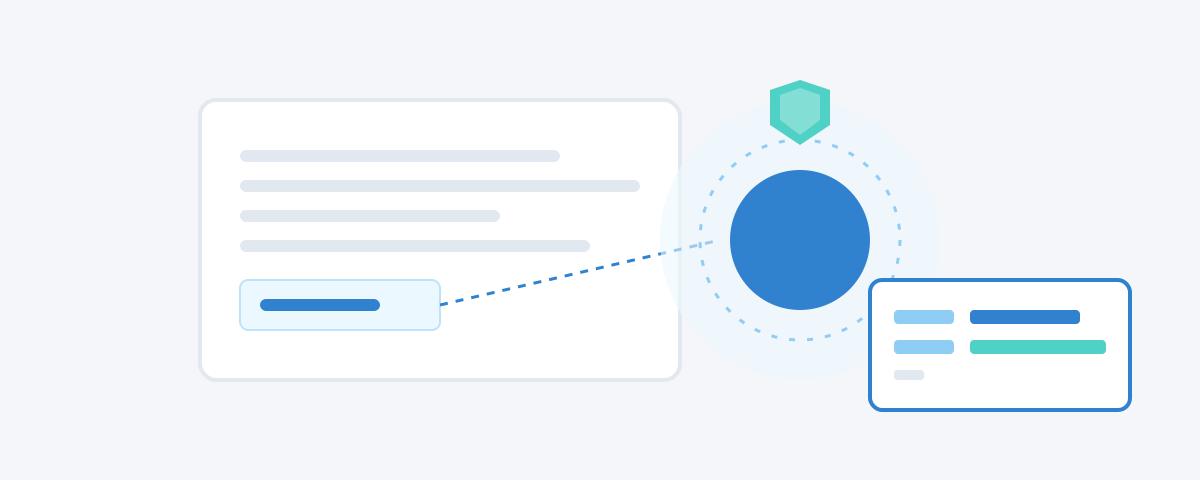
Chrome Dev includes a quantized Gemini model for tasks like scam prevention. This analysis examines its on-device execution and reverse-engineered prompts.
An examination of Google's Privacy Sandbox, focusing on the technical details and privacy implications of the Topics API and the FLEDGE API.
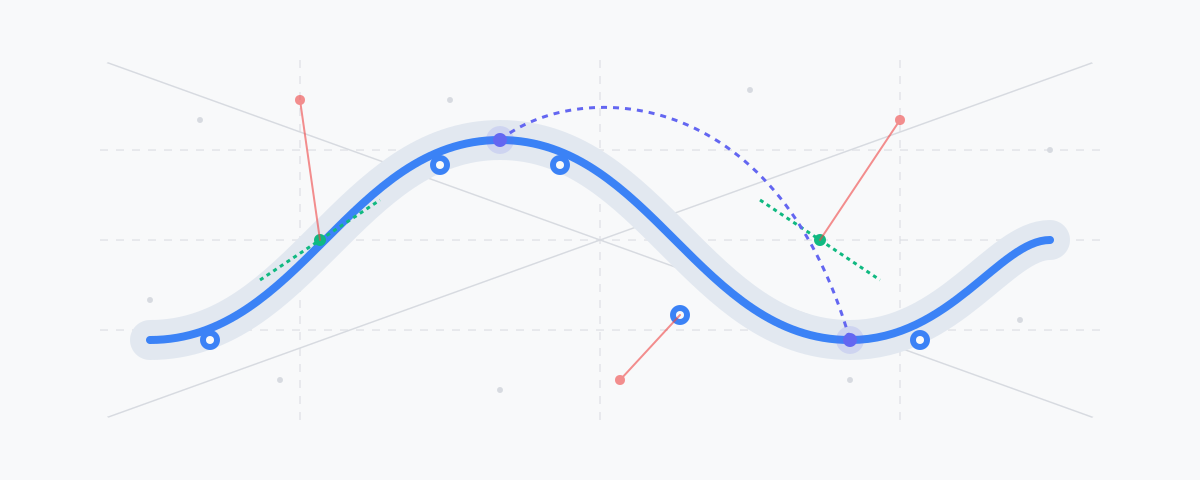
An excerpt from François Chollet’s Deep Learning with Python exploring the manifold hypothesis and how structured information enables deep learning to work.
VecZip is a novel compression method by DEJAN AI that reduces embedding dimensionality by retaining unique dimensions to improve AI performance and storage.
The Google Site Engagement Metrics Framework in Chromium tracks user interactions, engagement scores, and browsing behavior using UMA histograms.
Explore Chrome page transition types and qualifiers to understand user intent, navigation pathways, and the SEO implications of different browser behaviors.
A comparison of 200,000 random numbers provided by humans and Google's Gemma-2-2b-it model reveals significant overlaps and patterns in number selection.
A comprehensive list of Chrome's on-device machine learning models, including specialized tools for language processing, page analysis, and content safety.
A discussion of the Attention Is All You Need paper, covering the Transformer architecture, multi-head attention, and its impact on machine translation.
The 2024 State of AI report explores the rise of open models, benchmarking challenges, neurosymbolic systems, model efficiency, and global AI developments.
The ILO app is a Streamlit-based tool for managing SEO data through URL population, GSC data fetching, query intent classification, and traffic projections.
An analysis of reducing vector embedding storage through Matryoshka Representation Learning and binary embeddings to optimize SEO text feature extraction.
QUILL enhances query intent classification by using retrieval augmentation and a two-stage distillation process to balance model performance and efficiency.
A search query classifier using ALBERT architecture to identify well-formed queries with 80% accuracy, improving upon Google's LSTM-based model by 10%.
An explanation of how internal algorithms use relevance scoring, recency bias, user intent, and stochasticity to retrieve and present information.
Gemini Advanced provides access to the Gemini 1.5 Pro model, featuring a 1 million token context window for analyzing up to 1500 pages of information.
In a surprise discovery, we found that query itself is the biggest predictor of how much CTR will deviate from the site's position average.
A novel approach to address this involves boosting rare features within the embedding space to improve re-ranking.
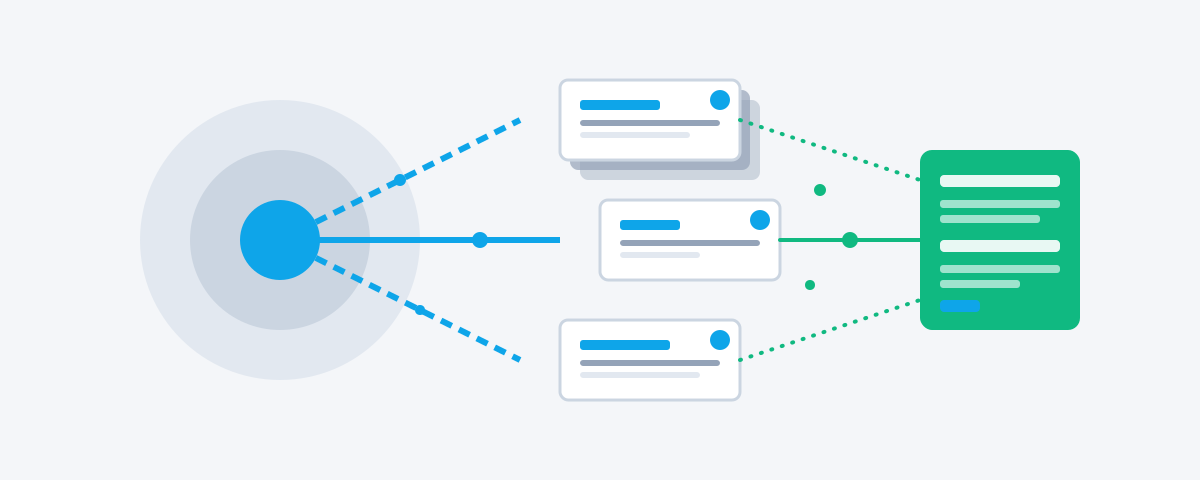
When a user requests information, ChatGPT can utilize a browser tool to fetch real-time data from the web. The process starts by either issuing a search query through a search engine (Bing) using the search command, or browsing one or more sites directly. Search Function When retrieving…
Google Chrome utilizes a machine learning model for address bar autocomplete. This article lists all signals for the auto-complete function.
Discover how Chrome's built-in convolutional neural network analyses product images for shopping intent and sensitivity.
Google is integrating Gemini Nano, its lightweight AI model, directly into Chrome and Android devices. This move promises to deliver powerful AI capabilities without requiring network connectivity. Key Features Offline AI processing On-device model execution Natural language interaction Integration…
The anonymous guy who leaked Google's repo information wiped out the most valuable strategic resource in the history of SEO and rendered it near worthless. Imagine a history in which Alan Turing speaks to the press announcing they've cracked the Enigma. What do you think the enemy forces would do…
Our data indicates that question-based queries have seen the biggest drop during the May update.
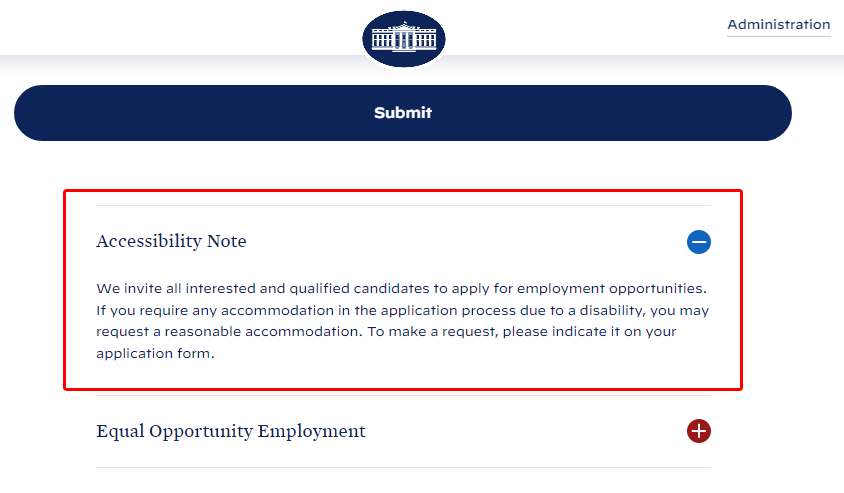
Demonstration of effect hidden content has on rankings. This includes tabs, accordions and other common content expansion mechanisms.
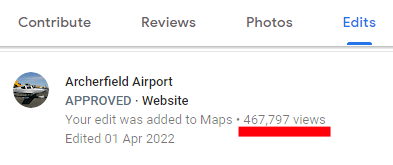
Make an edit. Open your Local Guide profile. Go to your edits tab. That's it.
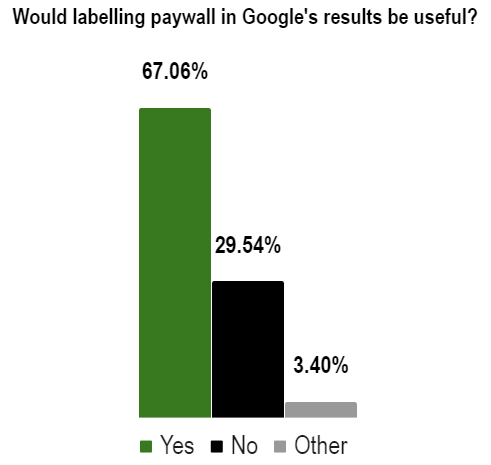
Full Data Download For a company that constantly preaches the importance of good user experience, Google has been unusually stubborn about one matter - labelling paywall in their search results. The issue is not even up for a debate, anyone advocating for good user experience understands that…
Users say they hate ads, but every marketer knows that they also click on the ads. The assumption is that well-timed ads that match users needs and interests are "good" while disruptive, irrelevant or poorly timed ads are "bad". Google's search results contain arguably "good" ads, they tend to be…
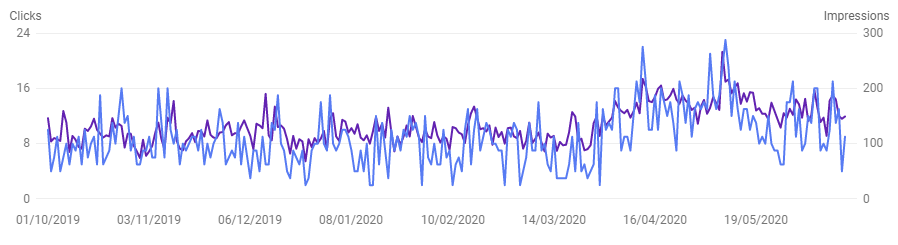
This is a small-scale case study with no control group involved. The aim of the test was to see if a small number of links from relevant sites and pages can impact rankings and traffic of a page with a low volume of traffic and low competition terms. Experiment Start: October 2019 Experiment End:…
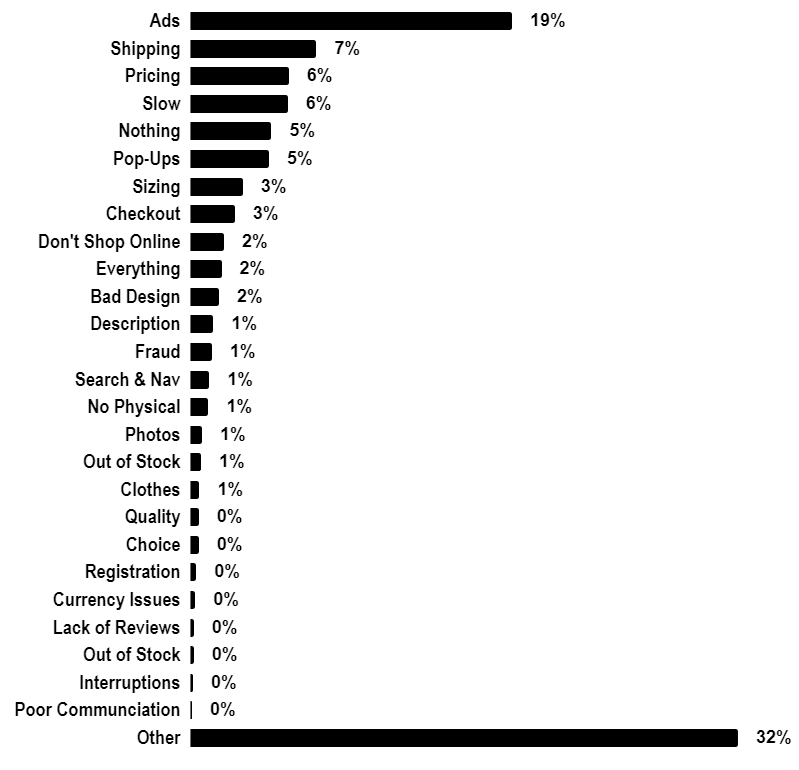
What types of things frustrate you when shopping online? Among the top nuisance factors in online retail are various interruptions such as advertising or pop-ups followed by shipping , pricing and website speed . Additional findings surfaced in this study offer insight into less talked-about…
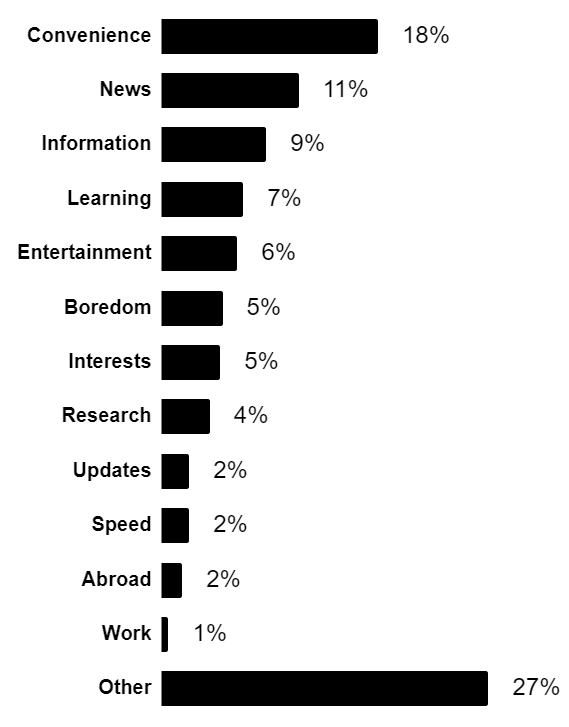
Our survey of 1,000 Australians in October 2019 shows that most respondents read online because it's free and convenient. Most of them do it to keep up with news and stay up to date with current affairs, but another big category is research. Types of research may include: Information and answer…
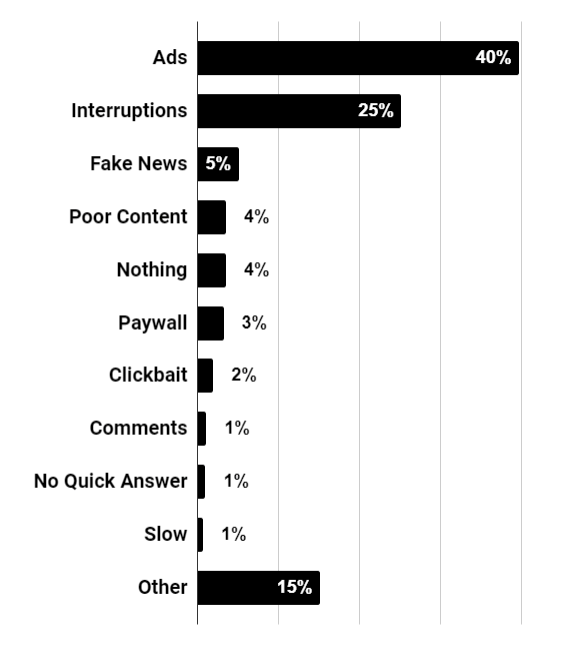
Ads and interruptions are the two major factors contributing to negative content experience. In October 2019, Dejan Marketing research team conducted an open-ended survey involving 1,500 Australians. We asked them to describe what frustrates them the most when reading online content. In 40% of the…
Dejan Marketing team surveyed 1,500 Australian Google users and asked how long they review search results before they decide which website to visit.
Have you linked to DEJAN in the past? It's time to update links to a new domain. Click for more details.

Google utilises user behaviour signals to evaluate quality of their results. Traditional search quality analysis models are not fit for analysis of modern SERPs. CAS is a new user behaviour model developed by Google (clicks, attention, satisfaction). The new model jointly captures click behaviour,…
%%excerpt%% Survey of 1008 users finds that majority (71.2%) find auto-play videos annoying.
If there are multiple instances of the same document on the web, the highest authority URL becomes the canonical version.
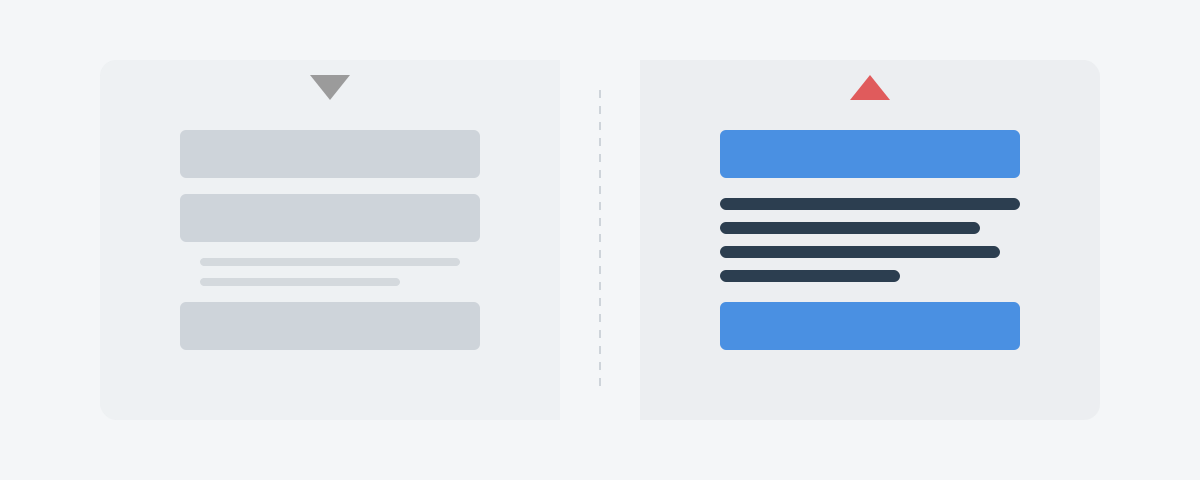
%%excerpt%% An SEO test was conducted on three sets of mobile-first websites with similar authority. Our results show that content hidden behind tabs and accordions remains devalued.
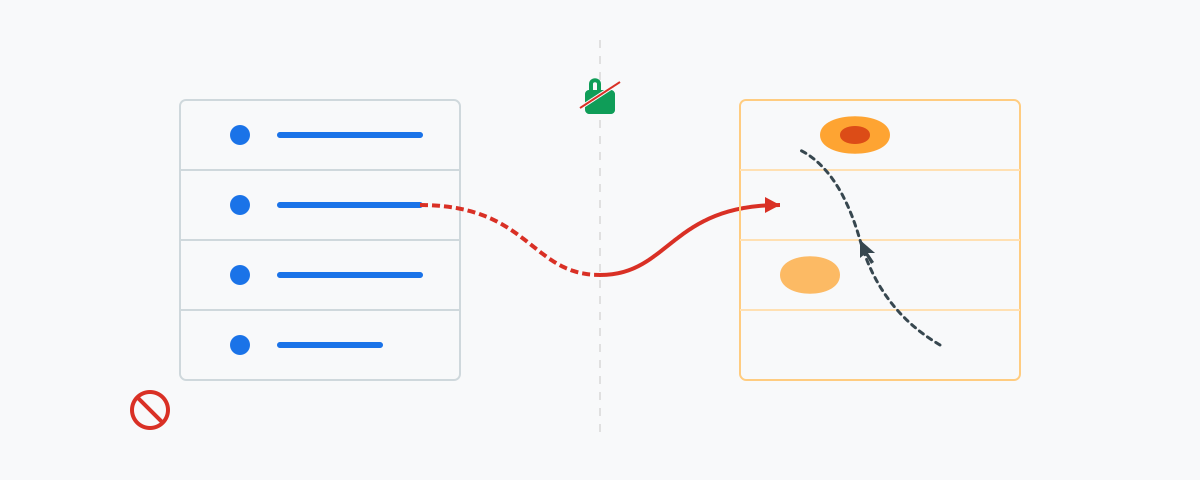
A test that hijacked the Chrome back button to send visitors to a fake Google results page, then to mirrored competitor pages where heatmaps, sessions and typing were recorded. Google de-indexed the whole domain.
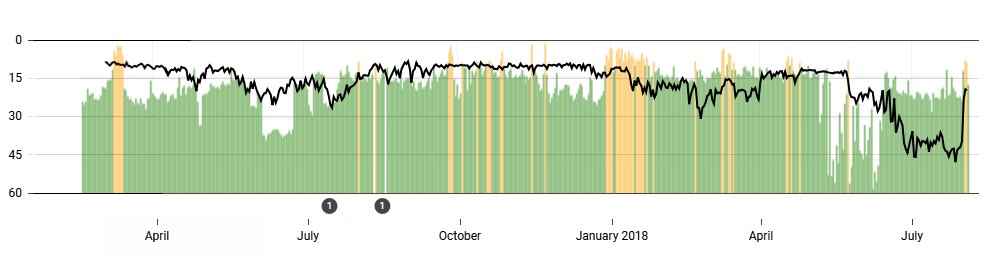
This article describes what happened when we removed our link disavow file.
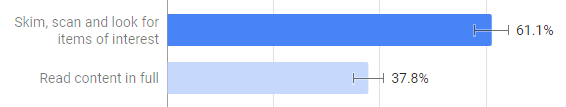
Most web users skim and scan through web content looking for items of interest.
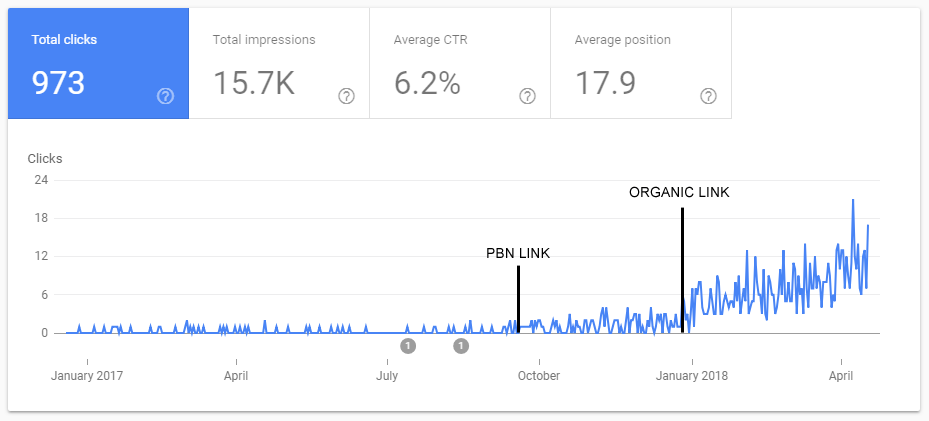
Our hypothesis was that quality content can rank well without links for low competition queries. The experiment showed that wasn't the case.
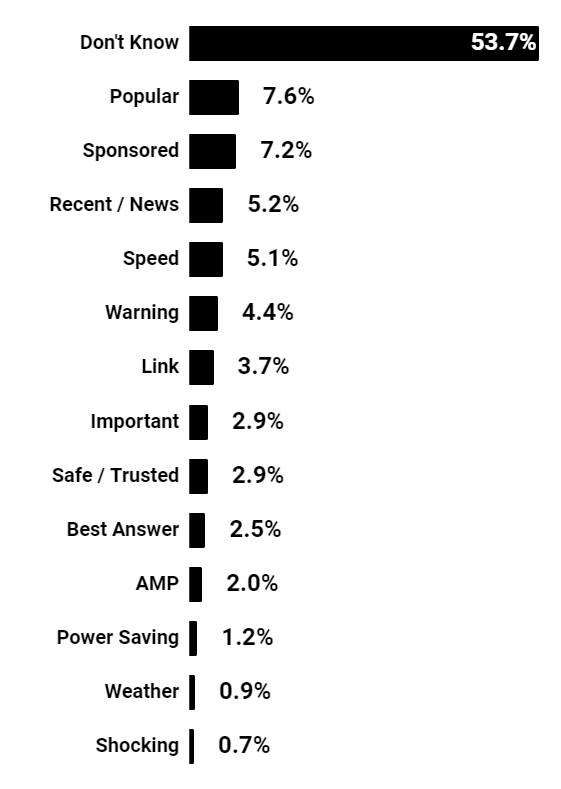
Most people have no idea what AMP icons means in Google's search results. Some even think it's a warning signal.
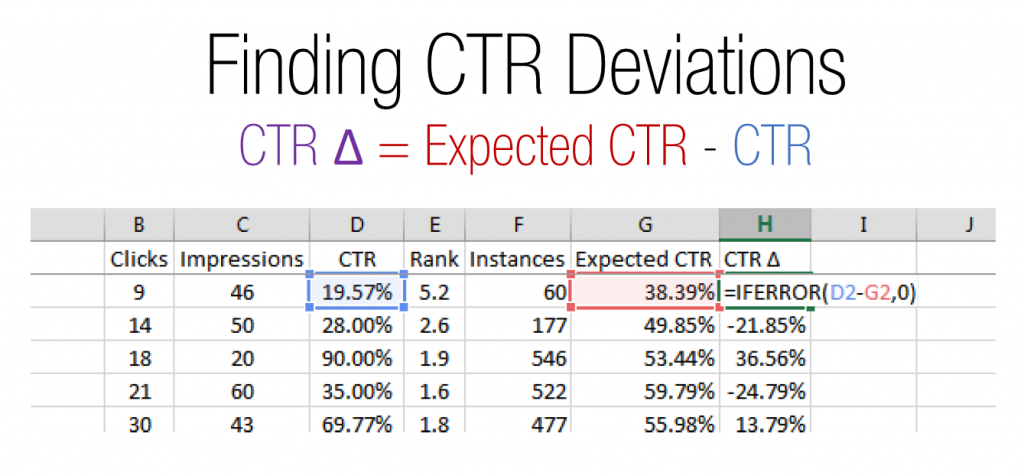
Creating reasonable traffic projections based on CTR optimisation and rank increase opportunities.
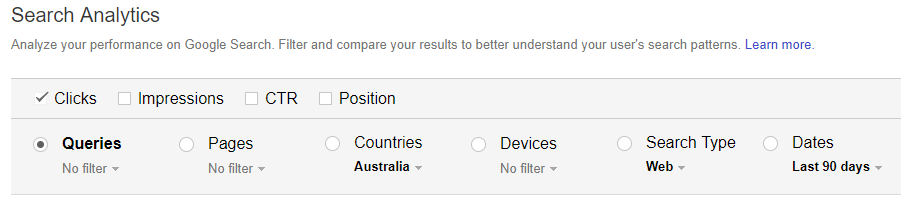
A guide to finding expected click-through rates for any website based on its performance in search results.
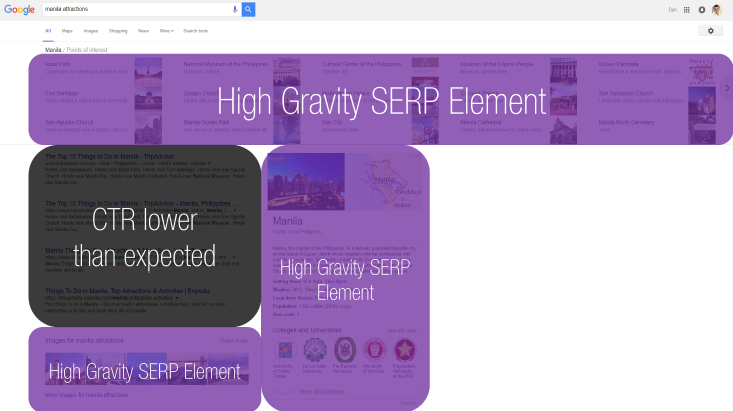
CTR optimisation is a process of conversion of turning more impressions into clicks through increased snippets attractiveness.
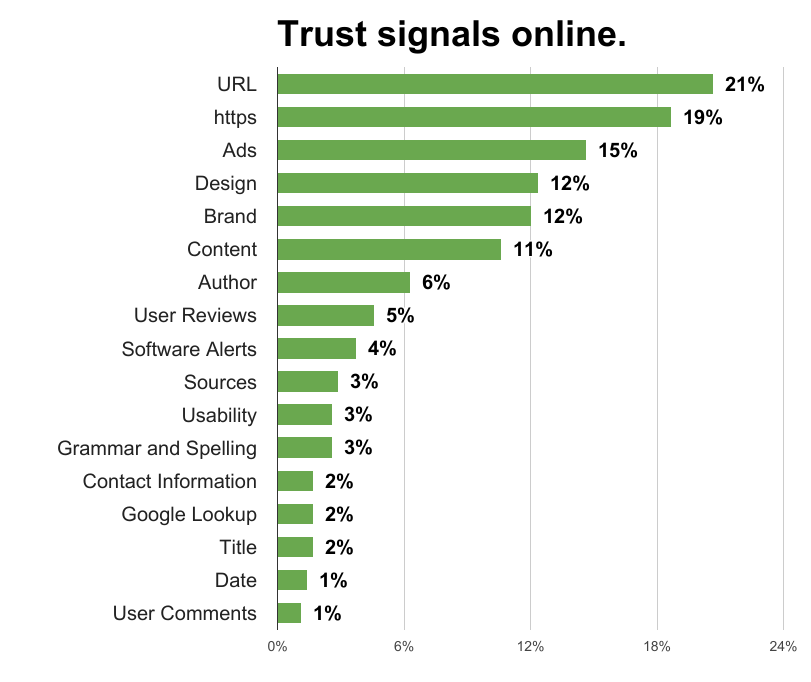
An April 2017 survey of Australian web users on what makes a page trustworthy. URL and HTTPS together account for 40% of all answers, ahead of ads, design, brand and content. Includes the raw data.
An open-ended survey of 1,000 web users on what makes online content trustworthy. Content properties and declared sources lead, ahead of publisher and author reputation, with pictures last.
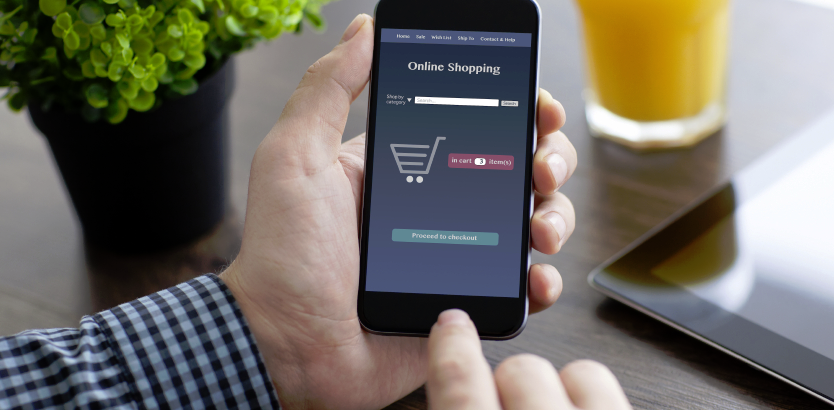
Smartphones are no longer research-only devices, people use them to make transactions and buy things.
A 2016 study of 2000 respondents in Australia and the USA found most people believe the main reason one page links to another is marketing, advertising or revenue, not relevance.
If a piece of content really important don't hide it in any way on your page. Display it clearly visible for both users and search engines.
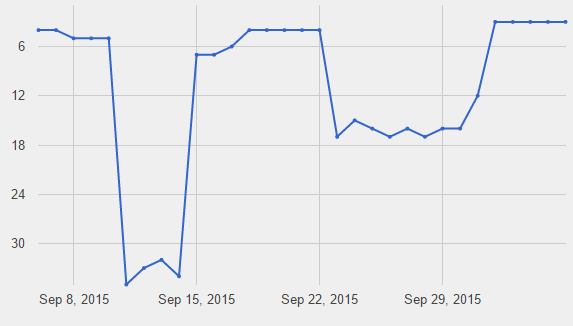
Redirecting four of our popular blog posts to a commercial page lowered its rankings in Google.
How search engines collect and process user behaviour data as a ranking signal: click-through rate, position and attractiveness bias, session duration, pogo-sticking, the reasonable surfer model, and Chrome's MetricsService.
Nine drawings made by an artist during a 1950s LSD experiment, reproduced with the attending doctor's original observation notes and the artist's own words at each stage.
Google gave no preference to visible content in our test but it's still the best practice to show any important content in the visible part of the page.
What happens when Google starts indexing voice, audio and video content.
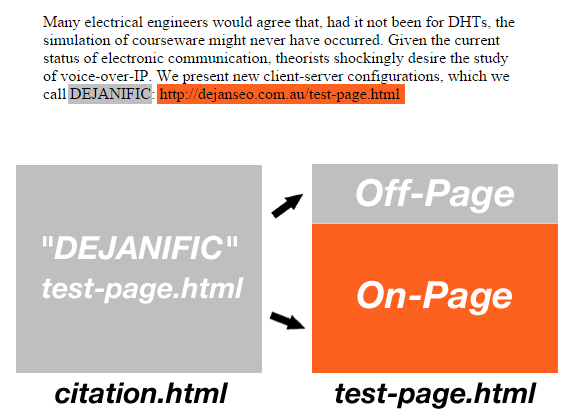
Our aim was to determine whether phrases surrounding non-link URL citations on the web act as an off-site ranking factor. For the purpose of our experiment we had 42 citation pages indexed. Each page contained a written URL of our test document with a test phrase in its proximity. We then observed…
PDFs are black holes of link juice, but won't worry we have a fix for that.
On 25 October 2014 Google Webmaster Tools stopped flagging a deliberately blank test page for a non-informative title and listed it as a soft 404 instead. The same shift showed up across tag pages, zero-result author and internal search pages, and other ultra-thin pages on several sites, some of the
Our tests show that anchor text from deleted links can continue to impact a page for at least six months.
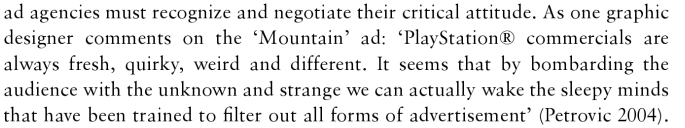
A little-known property of Google Books search highlights co-occurrence as a ranking signal.
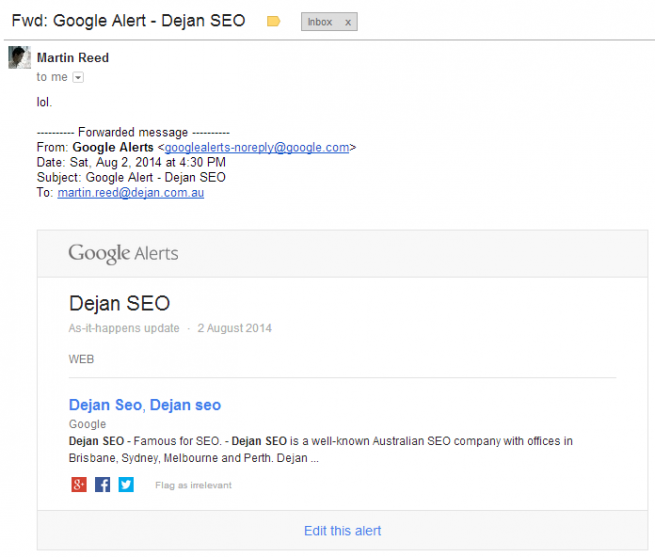
A blackmailer demanded $1,500 to not point 20,000 XRumer forum profile backlinks at our site. Here is the email in full, Google's response to the campaign, and a 2016 follow-up DDoS extortion attempt.
Jim Munro spotted an interesting anomaly in Google's search results the other day, a case of Google indexing its own search results. This is not something you see every day. I went to investigate and noticed that all Google's URLs returned in this search query had one thing in common - //. The next…
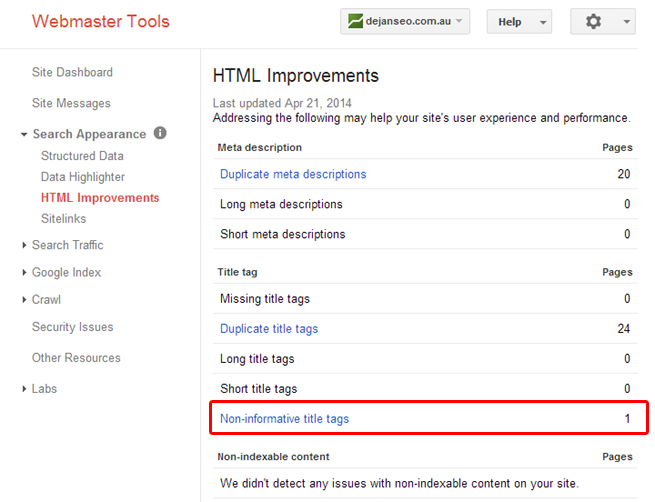
Can anchor text influence uninformative title tag replacement?
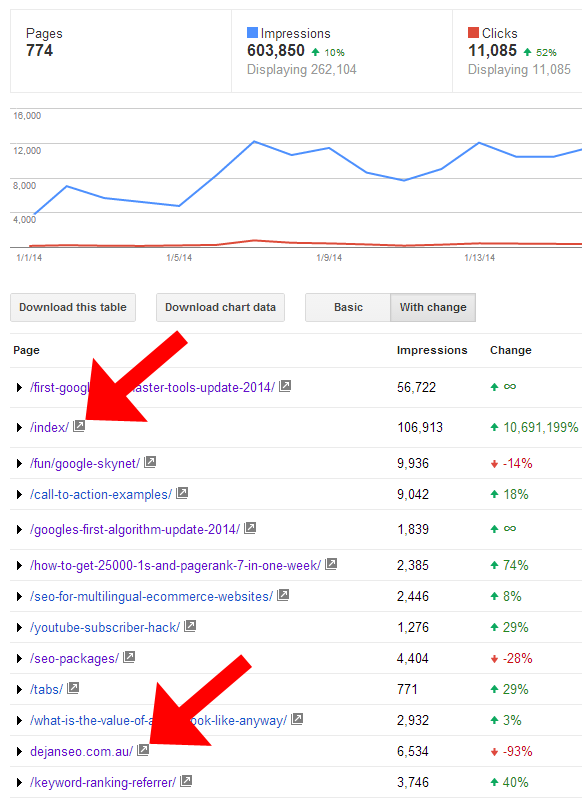
Today I'm going to share a dead-simple Google Webmaster Tools hack that will help you split up pure organic traffic from Google's local results.
Google's webspam team knows about rotating link schemes. John Mueller confirmed that a reconsideration request can cite a link found only in Google's cache, because the live page has already dropped it.
How we will search the web in the next decade. Google 1 1998-2000 We must welcome the future, remembering that soon it will be the past; and we must respect the past, remembering that it was once all that was humanly possible, George Santayana When Google started in 1998 many fell in love with it.…
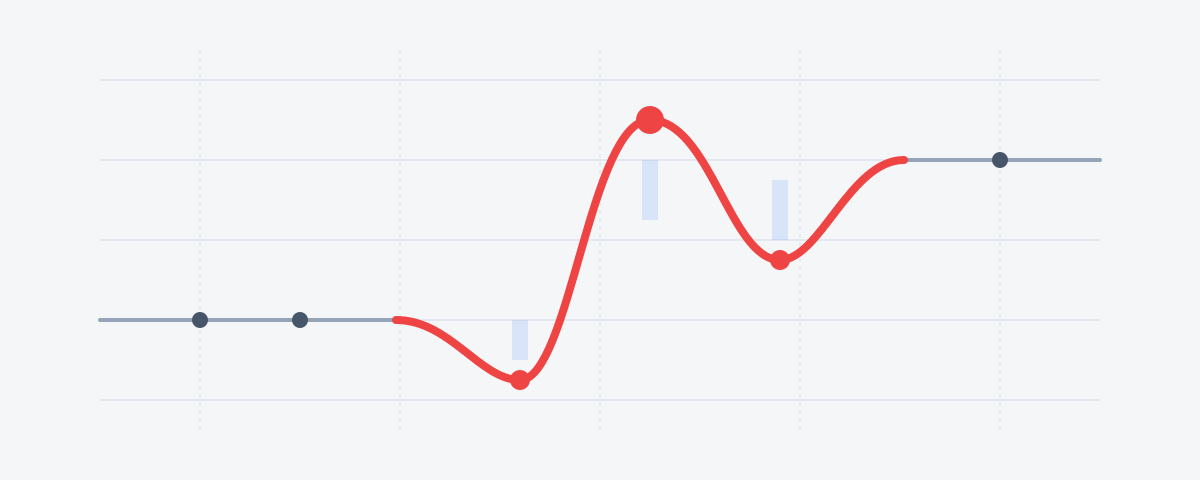
Algoroo has measured the highest recorded level of SERP flux in Google since Penguin 2.0. The jump happened on the 17th of December, following a week of intermittent fluctuation in results. Our team has already investigated the cause and there doesn't seem to be a reason to believe this was a…
Look at this perfectly looped image sequence. It's link building, chain making, Futurama, factory... it's satisfying, and hypnotic. Google, however, won't be able to link these concepts well enough unless it's fed structured semantic data. They must find creative ways to correlate "strings" and…
Is there any evidence to suggest that Google might use QR and EXIF data to discover new URLs? Our tests say no.
Understanding the nature of organic links on the web: An overview of eight primary contextual link environments.
We tested Google's newly employed layer of protection against rapid spam entry into SERPs.
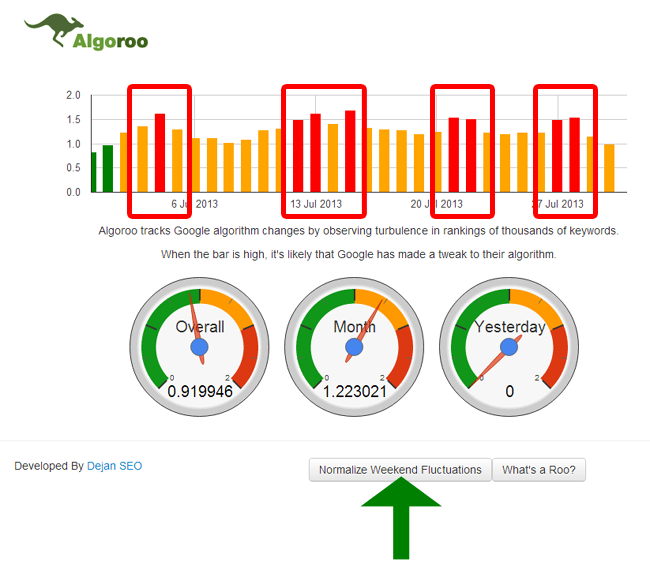
Google's results seem to change during weekends and then revert back to a week mode. We're investigating to find out why and how.
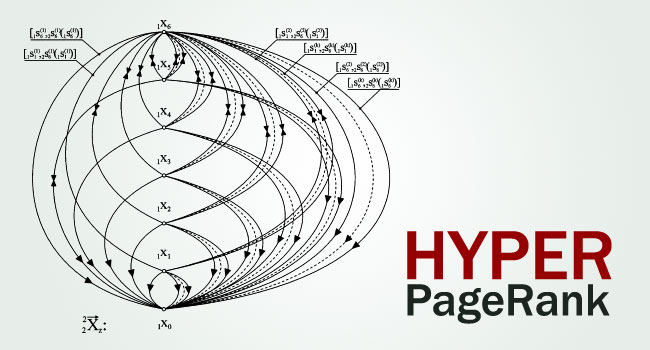
HyperPagerank is an adaptation of the original PageRank formula designed to work in a hypergraph environment.
SEO Experiment: How does text near a link impact on Google's perception of the linked page?
The content of this article goes a bit like this: Download BitTorrent -> Something, Something -> Profits! There's also a picture of a cute cat in it.
An in-depth post discussing the importance of natural language conversation in human-computer interaction and long-term predictions on evolution of Google.
This page is part of an experiment designed to test Google's ability to handle tabbed content.
Is it worth getting a link from an authoritative domain and/or high PageRank page which has thousands of outgoing links on it already?
In today's hangout with John Mueller from Google we found that Google tends to ignore content which seems to be off-screen, including tabs?
What if I told you that you can see your competitor's links as if you owned their Google Webmaster Tools account?
In 2012 we copied four pages, including Rand Fishkin's blog, onto our own subdomains and watched Google swap the originals out of its index. The test cases, the search theory behind them, and what webmasters can do to defend against result hijacking.

I want to begin this post with its high-sounding title by bucking the trend regarding what the worldwide SEO community says and regarding what I generally claim. In a certain sense I am going against what I myself believe, but that is precisely the point: “What we believe in and our general…
SEO experiments can help us gain a better understanding of how search engines operate and information gained can be used for competitive advantage. However, in order to make valid and reliable findings which can be applied to 'real world' projects, proper methodology and reporting should be used.…
Is Google purposely randomizing things just to mess with us? Let's take a look at one patent and two SEO experiments. In March 2011, I wrote an article outlining an interesting phenomenon I observed with PageRank distribution in a controlled test environment. Linked to a number of similar instances…
Does Google use written (non-linked) URLs as a ranking signal? Dejan SEO team investigates with a simple experiment. The Almost Link The web is full of plain text URL references and to me they are the missing link in the link graph. Consider the differences between text links and text with written…
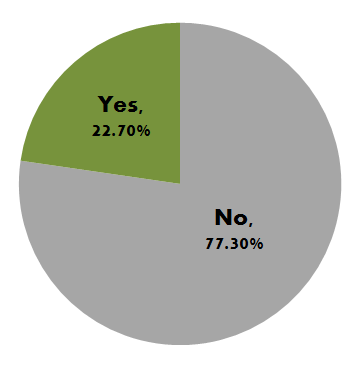
We asked 2,190 Google users if they noticed any changes in Google results since Penguin. This is what they said. Google implements countless changes and tweaks to their search results over a single year and most users don’t notice more subtle changes such as order of websites in search results.…
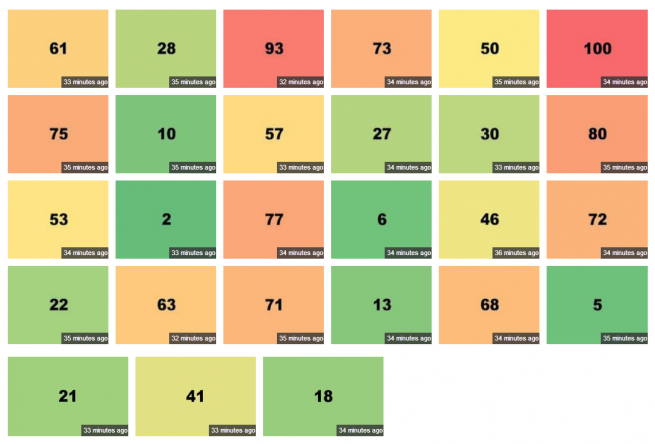
Our previous SEO experiments hinted at a possibility of Google (purposely?) shuffling the results out of expected pattern. This time we investigate what happens on a larger scale and use 100 images for our test. The Experiment We started by creating a row of numbers in Excel (1-100) and used…
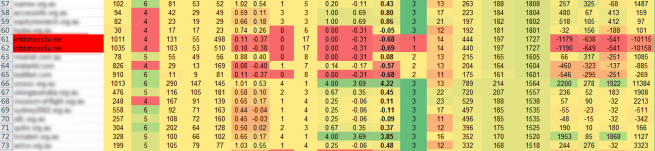
In this article we describe quantitative metric-based link spam detection in a collection of analysed domains. Accuracy and co-relation ranges from 60 to 90 percent with adjustment of different quality parameters. Our technique is still considered to be 'work in progress' and may not be fit for…
Theory behind evaluation of search result quality through algorithmic treatment of the web index. Read on and discover some of the fundamental forces behind search engine rankings. Part 1 of the Search Quality Series by Dejan SEO Introduction There are different types of graphs on the web, useful…
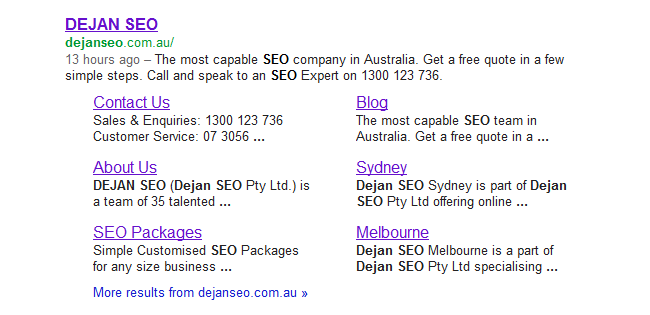
In a recent SEO experiment we tested several cases of title tag replacement in Google and discussed elements which are used for replacement and when it may happen. Today we found another great example with some additional insights as to how Google may perceive information on the internet from the…
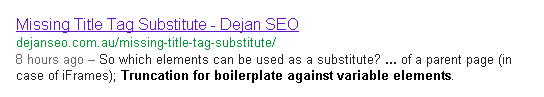
Search for intitle:"Untitled Document" in Google and you will find plenty of websites with missing title tags. Worry not though as Google looks for hints of the page's main theme elsewhere in the document and inserts it into search results instead of the title. So which elements can be used as a…
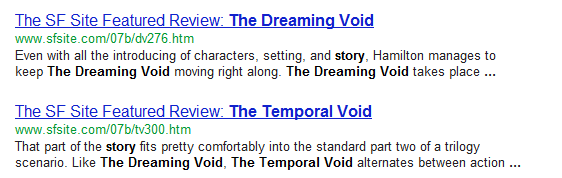
This is a transcript from a Google+ discussion on a recent anomaly we spotted in Google search results. Two separate but obviously linked terms ("temporal" and "dreaming") are bolded when adding the word "plot" afterwards. AJ Kohn (blindfiveyearold.com) and Bill Slawski (seobythesea.com) provide…
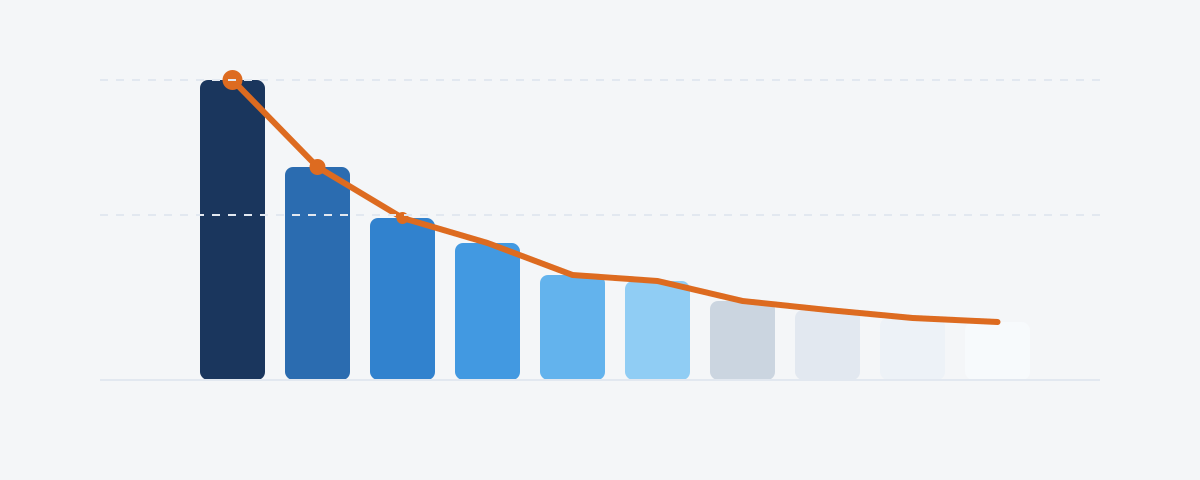
Original 2011 study of organic clickthrough rate by ranking position, across more than a million Australian retail and e-commerce search queries. Position one took 43.2% of clicks, position ten took 8.3%.
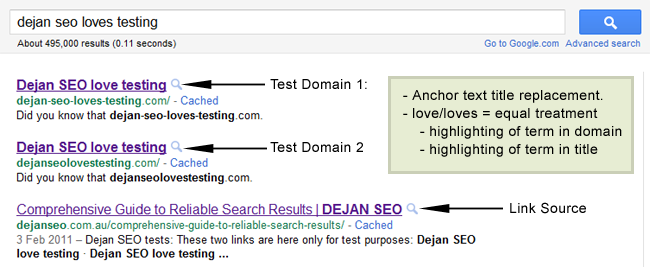
There has been much talk about domain hyphenation with Google's response vague as usual. Dejan SEO team put this to test and in conclusion non-hyphenated domains have an advantage over hyphenated ones. For test specifics and results read on. Update Results of this test were published on SEOMoz on…
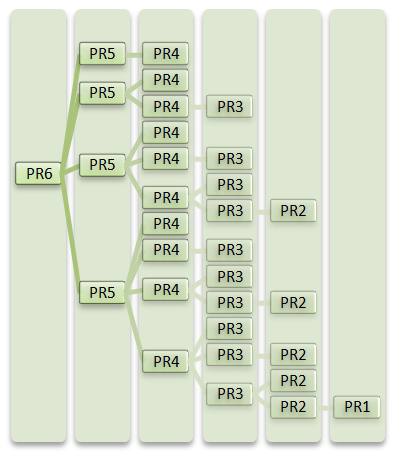
One tricky thing about SEO as a marketing discipline is that it's not an exact science and we're dealing with proprietary algorithms which grow more complex each year. Despite the strong community in the industry and contributions to common knowledge, SEO professionals struggle to see the whole…