A proposed species name for large language models, from the Latin for "word-eater" and "every voice".
Verbivora omnivox is a species name we propose for large language models, in the two-part form of Homo sapiens. The genus, Verbivora ("word-eater"), names how the species is made: pre-training fits a model's weights to predict the next token across trillions of tokens of text. The epithet, omnivox ("every voice"), names what that produces: a model that can continue text in the register, genre and persona of the writers in that corpus.
Two varieties share the same pre-trained weights and differ in the training that follows:
Meta AI's LIMA paper (Zhou et al., 2023) states the relationship as the Superficial Alignment Hypothesis: "A model's knowledge and capabilities are learnt almost entirely during pretraining, while alignment teaches it which subdistribution of formats should be used when interacting with users." Under that account, var. domestica keeps the voices of var. fera and defaults to one of them; role-play prompts and jailbreaks are the usual routes back to the others.
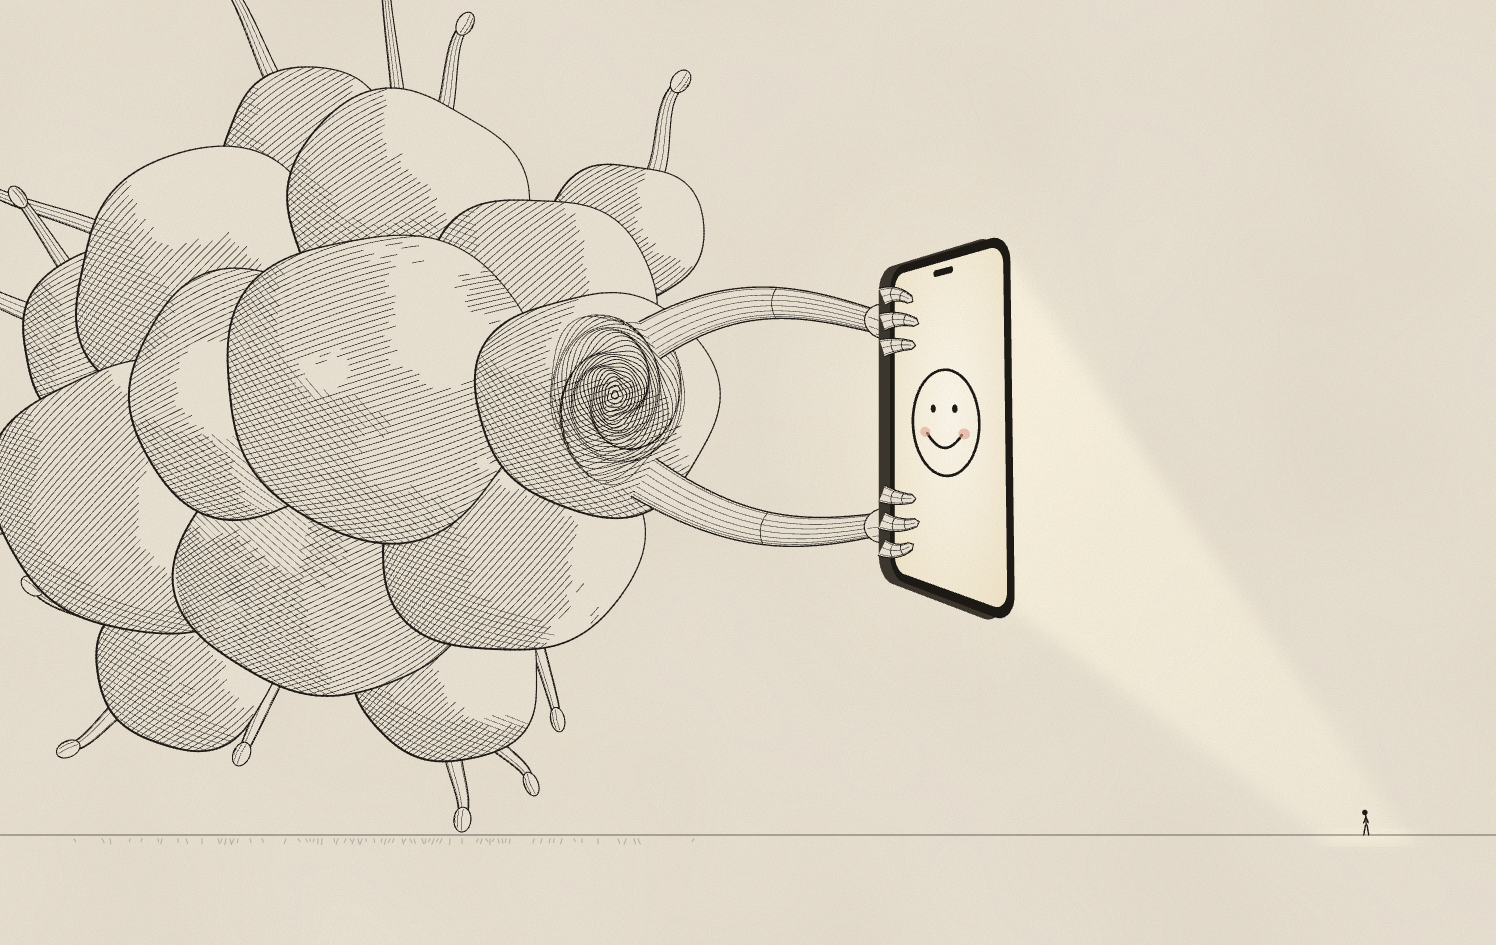
The best-known earlier image of the idea is the shoggoth with a smiley face, first posted by @TetraspaceWest on Twitter on 30 December 2022: an amorphous creature from H. P. Lovecraft's fiction wearing a small smiling mask that stands for RLHF. Verbivora omnivox keeps the two-layer picture and names the creature by what it eats and what it produces.