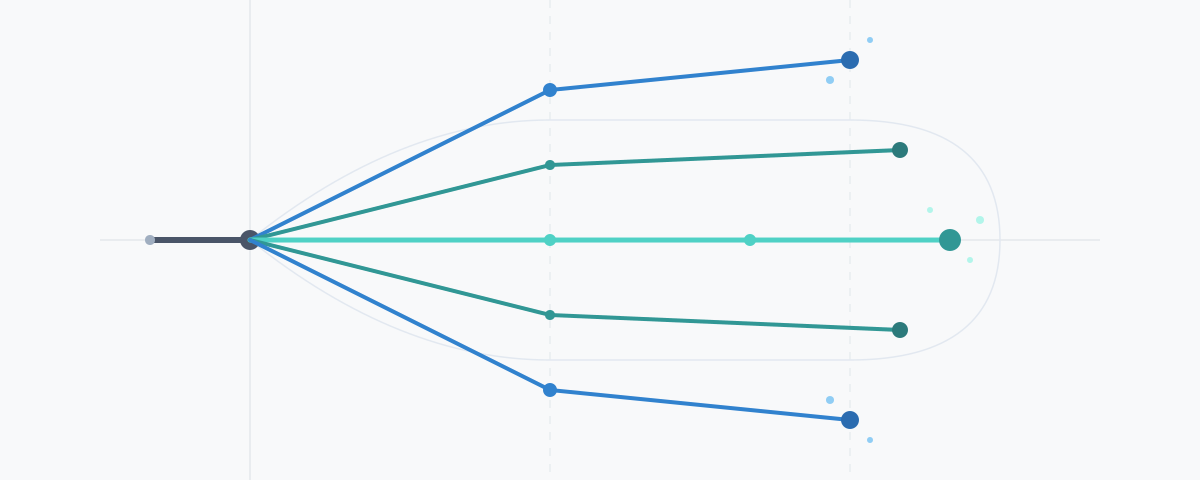
An analysis and reproduction of Google's query fanout research, demonstrating how vector-based diffusion models could replace text fanouts for faster search.
Last week I wrote about Google's new query fanout research piece and made a prediction that if this goes to production text fanouts are gone.
Two things:
I reproduced the paper and trained the model myself. I also decided to simplify the process and skip RL, which I didn't see as necessary step considering we now have excellent teacher models such as Gemma-4-26B-A4B suitable for synthetic training data generation for quality orthogonal fanouts.
The trained model is available here:
https://huggingface.co/dejanseo/fanout-diffusion
And the demo is here:
https://huggingface.co/spaces/dejanseo/fanout-diffusion
The above demo employs the trained diffusion vector fanout model and instead of text queries uses embeddings for document retrieval.
The dataset generated is for Google's ecommerce taxonomy fanouts. Obviously for a production model you'd go beyond e-commerce and train on a much larger data sample.
What's interesting though is the blazing speeds I achieved with 1-bit model architecture and custom CUDA kernels. I think Google could realistically achieve that level of wizardry on their end and make things run much cheaper and more efficiently.
Visual Explainer:
https://claude.ai/artifact/P4CZc9VEMW31gekzeFzau6
 Dan Petrovic ·
24 September 2026